


About Gemini 4 Hydrogen
Gemini 4 Hydrogen is Google's fast Gemini 4 model for everyday coding and agent tasks, released on November 12, 2026. It is built on Gemini 4 Carbon, reads up to 1 million tokens of text, images, audio, video and files and writes up to 64,000 tokens in one reply
Gemini 4 Hydrogen scores 51 on the Artificial Analysis Intelligence Index at its default thinking level, one point above Gemini 4 Argon, and 54 at the highest. It beats Claude Sonnet 5.5 and GPT-6.1 Terra on AutomationBench with 76.1% and on HLE-Diamond with 58.8%, and it finishes tasks 2.5 times faster than Gemini 3.8 Flash
On Overchat AI, Gemini 4 Hydrogen is in the model menu next to Gemini 4 Carbon and Gemini 4 Argon, so a quick task can go to Hydrogen and a hard one to Carbon in the same conversation
- Modalities
- Max output
- 64,000 tokens
- Context window?
- 1M tokens
- Released
- Nov 12, 2026
Compare Gemini 4 Hydrogen
Gemini 4 Hydrogen vs Claude Sonnet 5.5
Gemini 4 Hydrogen scores higher than Claude Sonnet 5.5 in 6 of 9 benchmarks. The widest lead is in Agents' Last Exam v1.1: 71.6% against 60.4%. Claude Sonnet 5.5 is ahead in Terminal-Bench-Science 0.1: 59.9% against 51.4%. Gemini 4 Hydrogen writes 243 tokens per second, Claude Sonnet 5.5 writes 102
- Benchmarks won
- Gemini 4 Hydrogen: 6
- Claude Sonnet 5.5: 3
- Average score
- Gemini 4 Hydrogen: 58.4%
- Claude Sonnet 5.5: 56.7%
- Output speed, tokens/s
- Gemini 4 Hydrogen: 243
- Claude Sonnet 5.5: 102
- Time to first token, s (log scale)
- Gemini 4 Hydrogen: 29.1
- Claude Sonnet 5.5: 1.0
- Agents' Last Exam v1.1+11.2
- SWE-sweep+10.4
- HLE-Diamond+5.5
- Chartography+5.0
- AutomationBench+4.3
- MKA+1.4
- OSWorld-2.1−6.3
- Terminal-Bench 4.1−6.9
- Terminal-Bench-Science 0.1−8.5
Gemini 4 Hydrogen vs GPT-6.1 Terra
Gemini 4 Hydrogen scores higher than GPT-6.1 Terra in 7 of 8 benchmarks. The widest lead is in AutomationBench: 76.1% against 60.2%. GPT-6.1 Terra is ahead in Terminal-Bench-Science 0.1: 58.3% against 51.4%. Gemini 4 Hydrogen writes 243 tokens per second, GPT-6.1 Terra writes 75
- Benchmarks won
- Gemini 4 Hydrogen: 7
- GPT-6.1 Terra: 1
- Average score
- Gemini 4 Hydrogen: 58.6%
- GPT-6.1 Terra: 52.8%
- Output speed, tokens/s
- Gemini 4 Hydrogen: 243
- GPT-6.1 Terra: 75
- Time to first token, s (log scale)
- Gemini 4 Hydrogen: 29.1
- GPT-6.1 Terra: 4.3
- AutomationBench+15.9
- HLE-Diamond+11.5
- MKA+9.6
- SWE-sweep+7.7
- OSWorld-2.1+3.4
- Chartography+3.4
- Agents' Last Exam v1.1+1.8
- Terminal-Bench-Science 0.1−6.9
- Terminal-Bench 4.1—
Best model by use case
Average benchmark scores of Gemini 4 Hydrogen and 2 other models by use case
Coding
?SWE-sweep- 1Gemini 4 Hydrogen13.5%
- 2GPT-6.1 Terra5.8%
- 3Claude Sonnet 5.53.1%
Agents
?Average of 3 tests- 1Gemini 4 Hydrogen75.1%
- 2Claude Sonnet 5.572.0%
- 3GPT-6.1 Terra68.1%
Knowledge work
?Average of 2 tests- 1Gemini 4 Hydrogen60.0%
- 2Claude Sonnet 5.556.8%
- 3GPT-6.1 Terra53.5%
Reasoning
?Average of 2 tests- 1Claude Sonnet 5.556.6%
- 2Gemini 4 Hydrogen55.1%
- 3GPT-6.1 Terra52.8%
Gemini 4 Hydrogen benchmarks
Compare Gemini 4 Hydrogen with Claude Sonnet 5.5 and GPT-6.1 Terra in 9 benchmarks measuring coding, agents, knowledge work and reasoning
Coding
- SWE-sweep?Gemini 4 Hydrogen13.5%Claude Sonnet 5.53.1%GPT-6.1 Terra5.8%13.5%+7.7
- Terminal-Bench 4.1?Gemini 4 Hydrogen57.0%Claude Sonnet 5.563.9%GPT-6.1 Terra—57.0%−6.9
Agents
- Agents' Last Exam v1.1?Gemini 4 Hydrogen71.6%Claude Sonnet 5.560.4%GPT-6.1 Terra69.8%71.6%+1.8
- AutomationBench?Gemini 4 Hydrogen76.1%Claude Sonnet 5.571.8%GPT-6.1 Terra60.2%76.1%+4.3
- OSWorld-2.1?Gemini 4 Hydrogen77.6%Claude Sonnet 5.583.9%GPT-6.1 Terra74.2%77.6%−6.3
Knowledge work
- MKA?Gemini 4 Hydrogen53.4%Claude Sonnet 5.552.0%GPT-6.1 Terra43.8%53.4%+1.4
- Chartography?Gemini 4 Hydrogen66.6%Claude Sonnet 5.561.6%GPT-6.1 Terra63.2%66.6%+3.4
Reasoning
- Terminal-Bench-Science 0.1?Gemini 4 Hydrogen51.4%Claude Sonnet 5.559.9%GPT-6.1 Terra58.3%51.4%−8.5
- HLE-Diamond?Gemini 4 Hydrogen58.8%Claude Sonnet 5.553.3%GPT-6.1 Terra47.3%58.8%+5.5
Sources: Google, Introducing Gemini 4 Hydrogen (Nov 12, 2026), Google, Gemini 4 Hydrogen for developers (Nov 12, 2026), Google DeepMind, Gemini 4 Hydrogen model card
Gemini 4 Hydrogen speed
Output speed is how fast the model writes (tokens per second, higher is better). Time to first token is how long you wait before the answer starts (lower is better)
Output speed and time to first token of 36 models
?Percentile| Models | Output speed, tokens/s (log scale) | Time to first token, s (log scale) |
|---|---|---|
| GPT-6 Luna | 143 | 2.4 |
| GPT-6.1 Terra | 75 | 4.3 |
| GPT-6.1 Sol | 58 | 2.9 |
| GPT-6 Astra | 48 | 3.2 |
| Claude Opus 5.5 | 88 | 1.9 |
| Claude Opus 5 | 54 | 2.6 |
| Claude Opus 4.8 | 59 | 1.3 |
| Claude Fable 5.2 | 84 | 2.3 |
| Claude Sonnet 5.5 | 102 | 1 |
| Claude 5 Sonnet | 215 | 10.5 |
| Claude Sonnet 4.6 | 220 | 10.8 |
| Claude Haiku 5.5 | 167 | 2.1 |
| Gemini 4 Carbon | 169 | 29.5 |
| Gemini 4 Hydrogen | 243 | 29.1 |
| Gemini 4 Argon | 91 | 6 |
| Gemini 3.8 Flash | 203 | 7.5 |
| Gemini 3 Pro | 270 | 11.2 |
| Grok 4.7 | 81 | 8.9 |
| Grok 4.6 | 290 | 32 |
| Qwen 3.8 Max | 81 | 30.6 |
| DeepSeek V4 Pro | 144 | 1.1 |
| DeepSeek V4.1 Flash | 422 | 2.2 |
| Mistral Large 4 | 226 | 8.6 |
| Hy4 | 214 | 37.7 |
| ERNIE 5.5 Flash | 405 | 2.7 |
| Muse Wonder | 980 | 8.7 |
| Muse Spark | 1129 | 6.2 |
| Kimi K3.1 Pro | 340 | 7.4 |
| Kimi K3 | 338 | 5.9 |
| GLM 5.3 | 197 | 1.2 |
| Flint | 194 | 12.3 |
| Llama 4 | 81 | 0.7 |
| Claude 4.5 Haiku | 162 | 0.9 |
| MiniMax M3 | 169 | 4.5 |
| MiniMax M3.1 Flash | 656 | 7.2 |
| Kimi K2.7 Code | 455 | 3.6 |
Typing test
Every model writes the same answer. The test waits the model's time to first token, then prints the text at the model's output speed and shows the total time
 Gemini 4 Hydrogen243 tokens/s29.1 s to first token
 Claude Sonnet 5.5102 tokens/s1.0 s to first token
 GPT-6.1 Terra75 tokens/s4.3 s to first token
Source: Overchat AI, 2026-11-12
See how Gemini 4 Hydrogen answers
Examples of Gemini 4 Hydrogen answers to 3 prompts: Fix a bug, Write a SQL query and Build a formula. Each answer is the unedited output of the model
This function should return the top 3 customers by total spend, but it returns the wrong people. Find the bug and fix only what's wrong. ```python def top_customers(orders): totals = {} for o in orders: totals[o['customer']] = o['amount'] ranked = sorted(totals.items(), key=lambda x: x[1]) return [name for name, _ in ranked[:3]] ```
Gemini 4 HydrogenThere are two bugs in the function:
- Overwriting instead of summing:
totals[o['customer']] = o['amount']replaces a customer's previous order amount instead of adding to their total spend. - Ascending sort order:
sorted(...)defaults to ascending order, soranked[:3]returns the 3 lowest-spending customers instead of the top 3.
Here is the corrected function:
def top_customers(orders):
    totals = {}
    for o in orders:
        totals[o['customer']] = totals.get(o['customer'], 0) + o['amount']
    ranked = sorted(totals.items(), key=lambda x: x[1], reverse=True)
return [name for name, _ in ranked[:3]]Write a PostgreSQL query: monthly revenue for 2026 and the change from the previous month in percent. Tables: orders(id, customer_id, created_at, status), order_items(order_id, product_id, quantity, unit_price). Only orders with status 'paid' count.
Gemini 4 HydrogenWITH months AS (
SELECT generate_series(
DATE '2025-12-01',
DATE '2026-12-01',
INTERVAL '1 month'
)::date AS month_start
),
raw_monthly_revenue AS (
SELECT
date_trunc('month', o.created_at)::date AS month_start,
SUM(oi.quantity * oi.unit_price) AS revenue
FROM orders o
JOIN order_items oi ON oi.order_id = o.id
WHERE o.status = 'paid'
AND o.created_at >= '2025-12-01'
AND o.created_at < '2027-01-01'
GROUP BY 1
),
monthly_revenue AS (
SELECT
m.month_start,
COALESCE(r.revenue, 0) AS revenue
FROM months m
LEFT JOIN raw_monthly_revenue r ON r.month_start = m.month_start
),
with_prev AS (
SELECT
month_start,
revenue,
LAG(revenue) OVER (ORDER BY month_start) AS prev_revenue
FROM monthly_revenue
)
SELECT
TO_CHAR(month_start, 'YYYY-MM') AS month,
revenue,
ROUND(
(revenue - prev_revenue) * 100.0 / NULLIF(prev_revenue, 0),
2
) AS mom_change_pct
FROM with_prev
WHERE month_start >= DATE '2026-01-01'
ORDER BY month_start;Key details handled
- Zero-revenue months:
generate_seriesensures every month in 2026 is present soLAG()always compares against the true prior calendar month rather than skipping months with no paid orders. - January 2026 baseline: Starting at
2025-12-01lets January 2026 compute its change against December 2025 before filtering the final output to 2026. (If you want January 2026 to always beNULL, change both2025-12-01references to2026-01-01.) - Division by zero:
NULLIF(prev_revenue, 0)returnsNULLinstead of an error if the previous month had0revenue. - Index-friendly date filter: Filtering
o.created_atwith>=and<allows PostgreSQL to use an index onorders(created_at)if one exists.
Write one Google Sheets formula for cell E2: the sales commission on the amount in D2. 0% up to $5,000, 5% on the part from $5,000 to $20,000 and 8% on everything above $20,000.
Gemini 4 HydrogenPut this formula in cell E2:
=MAX(0, MIN(D2, 20000) - 5000) * 0.05 + MAX(0, D2 - 20000) * 0.08How it works:
MAX(0, MIN(D2, 20000) - 5000) * 0.05: Calculates 5% only on the portion ofD2between $5,000 and $20,000 (up to a maximum of $15,000).MAX(0, D2 - 20000) * 0.08: Calculates 8% on any amount above $20,000.- Anything at or below $5,000 evaluates to
$0.
More prompts to try with Gemini 4 Hydrogen
What Gemini 4 Hydrogen is best for
Everyday coding
Paste a bug, a failing test or a small feature request, and Gemini 4 Hydrogen changes only the lines that need it. It scores 13.5% on SWE-sweep, more than twice GPT-6.1 Terra at 5.8% and four times Claude Sonnet 5.5
Agents and workflows
Give Gemini 4 Hydrogen a task with many steps, and it plans them, calls tools and recovers when a step fails. It scores 76.1% on AutomationBench and 71.6% on Agents' Last Exam, ahead of Claude Sonnet 5.5 and GPT-6.1 Terra on both
Data, charts and spreadsheets
Show Gemini 4 Hydrogen a chart, a table or a spreadsheet, and it finds the trend, writes the formula or the SQL query and checks the numbers. It scores 66.6% on Chartography and 53.4% on MKA, the best results in its table
Hard questions
Ask a hard question in science, finance or law, and Gemini 4 Hydrogen works through it step by step. It scores 58.8% on HLE-Diamond, ahead of Claude Sonnet 5.5 at 53.3% and GPT-6.1 Terra at 47.3%
How to use Gemini 4 Hydrogen on Overchat AI
Start in the chat at the top of this page or in the Overchat AI app on the web, iOS or Android
- 01
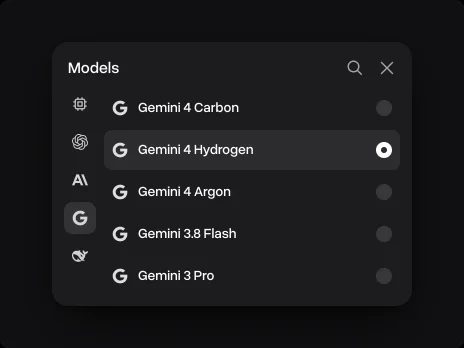
Pick Gemini 4 Hydrogen
It is already picked in the chat on this page. In the Overchat AI app, open the model list next to the message field and pick Gemini 4 Hydrogen
- 02
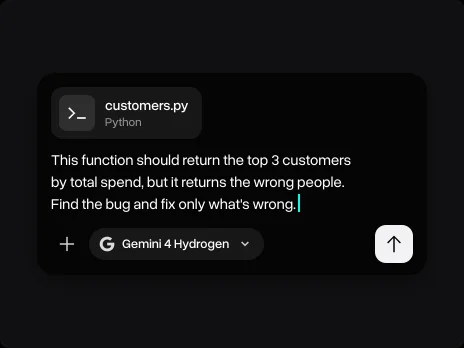
Attach your code or a file
Add code, a document, a spreadsheet or a screenshot, and write what you need: the result, the format and what must stay the same
- 03
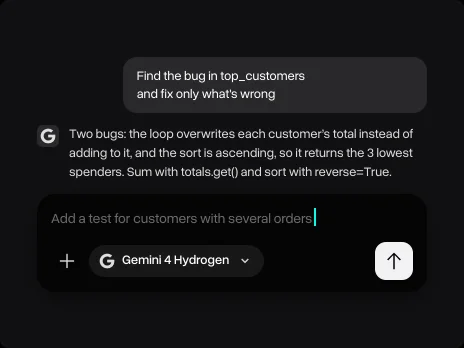
Keep going in the same chat
Ask a follow-up, ask for tests or a shorter version, or switch to another model without losing the conversation
Why use Gemini 4 Hydrogen on Overchat AI
One account for chat, images and video, on every device
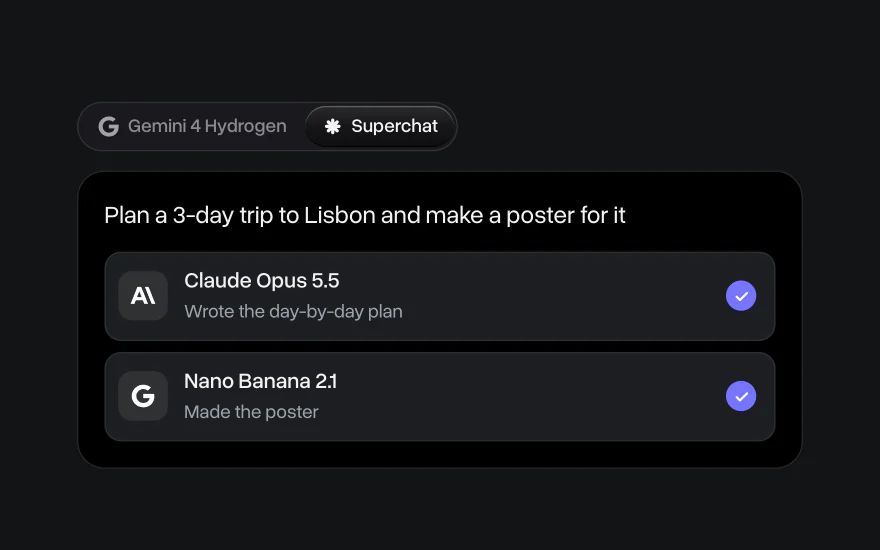
Superchat AI agent
Superchat Agent automatically routes your message to the model best suited for the task. It can generate images and videos, use the AI tools built into Overchat AI, and learn from your interactions to get better over time
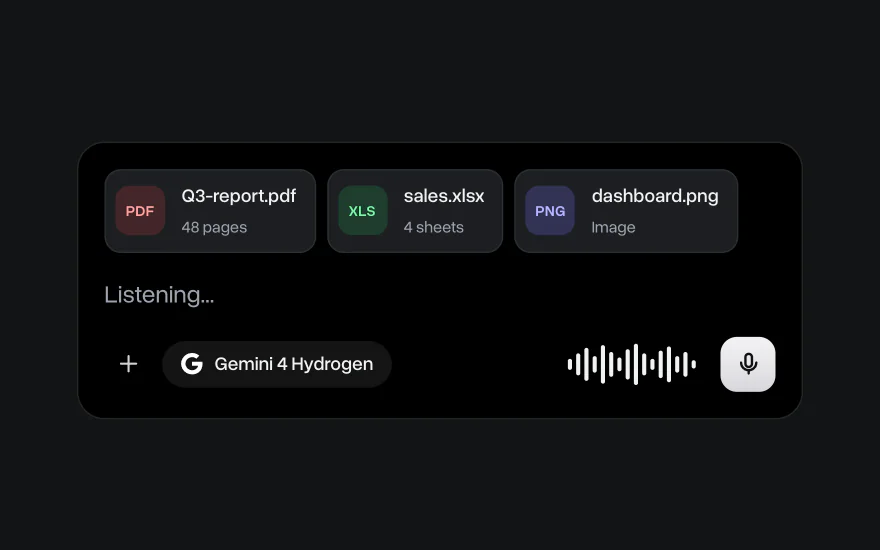
Chat with images and files
Upload PDFs, spreadsheets, code and screenshots and ask Gemini 4 Hydrogen about them. You can also dictate a message instead of typing it
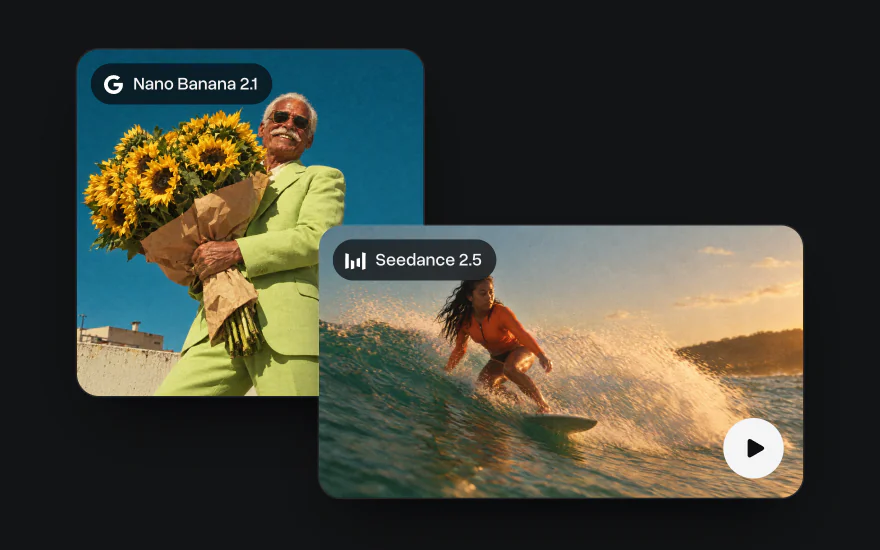
Go beyond text
Generate images with Nano Banana and GPT Image and videos with Seedance and Kling in the same account, with the same credits as chat
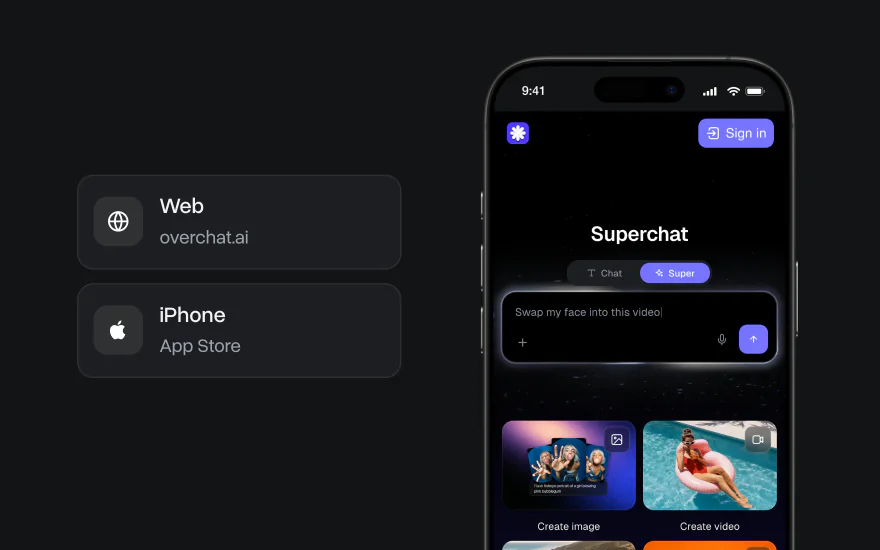
On the web and iPhone
Start a chat on your laptop and finish it on your phone. The Overchat AI app has the same models, and your chats stay in one account on every device
Gemini models on Overchat AI
Compare 5 Gemini models on Overchat AI by output speed, time to first token and the price of one message
Gemini 4 HydrogenThis pageGemini 3.8 FlashGemini 3 ProSource: Overchat AI, 2026-11-12
Explore other models
Models marked Soon are coming to Overchat AI; the rest are available now


Learn more about AI models

We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder
We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder on three coding tasks. See benchmarks, speed and how to use it
Muse Wonder vs Muse Spark: Meta's New Model Tested
We tested Muse Wonder against Muse Spark 1.3 on logic, writing and coding tasks. See benchmarks and which Meta model is better
10 Best All-in-One AI Platforms in 2026: Why One AI Subscription Beats Many
Compare the 10 best all-in-one AI platforms in 2026, from Overchat AI to Poe and Magai, with prices, free plans and the newest GPT and Claude models



