


About Qwen 3.8 Max
Qwen 3.8 Max is Alibaba's most capable Qwen model, built for coding, research and long tasks. It has 2.4 trillion parameters, of which 95 billion work on each token, reads up to 1 million tokens of text, images and video in one conversation and thinks before it answers. This is its September 2 update, with stronger coding and agents
Qwen 3.8 Max scores 88.8% on Terminal-Bench 2.1, fifth of 140 models, and 92.8% on GPQA Diamond, a test of graduate-level science questions. It can stay on one task for days: it rebuilt a research paper's experiments from scratch in about five days and then found a method that beats the paper's own
On Overchat AI, Qwen 3.8 Max is in the same chat as Claude Opus 5.5, GPT-6 and DeepSeek, so you can compare answers and switch models without starting over
- Modalities
- Intelligence Index?
- 33.7
- Context window?
- 1M tokens
- Released
- Sep 2, 2026
Qwen 3.8 Max vs other models
Qwen 3.8 Max ranks #19 on the Artificial Analysis Intelligence Index out of 54 models
- 59.1
 Claude Opus 5.5
- 54.6
 GPT-6.1 Sol
- 54.5Claude Sonnet 5.5
- 50.4
 Gemini 4 Argon
- 46.5
 Kimi K3.1 Pro
- 35.5
 Grok 4.7
- 34.6
 Hy4
- 33.7
 Qwen 3.8 Max
- 32.6
 DeepSeek V4.1 Flash
- 31.7
 GLM 5.3
- #5of 140 modelsTerminal-Bench 2.1Coding tasks an agent completes in a terminal
- #6of 131 modelsτ-Bench BankingCustomer requests an agent handles with a bank's tools and rules
- #12of 166 modelsGDPval-AATasks from real jobs, graded against experts' work
- #15of 325 modelsGPQA DiamondGraduate-level questions in physics, chemistry and biology
Source: Artificial Analysis
Compare Qwen 3.8 Max
Qwen 3.8 Max vs GLM 5.3
Qwen 3.8 Max scores higher than GLM 5.3 in 5 of 11 benchmarks. The widest lead is in Terminal-Bench 2.1: 88.8% against 83.9%. GLM 5.3 is ahead in SciCode: 59.0% against 52.1%. Qwen 3.8 Max writes 81 tokens per second, GLM 5.3 writes 197
- Benchmarks won
- Qwen 3.8 Max: 5
- GLM 5.3: 6
- Average score
- Qwen 3.8 Max: 50.8%
- GLM 5.3: 52.0%
- Output speed, tokens/s
- Qwen 3.8 Max: 81
- GLM 5.3: 197
- Time to first token, s (log scale)
- Qwen 3.8 Max: 30.6
- GLM 5.3: 1.2
- Terminal-Bench 2.1+4.9
- Terminal-Bench-Science+2.4
- GPQA Diamond+1.1
- Humanity's Last Exam+0.8
- AA-LCR+0.6
- CritPt−1.4
- τ-Bench Banking−2.5
- AA-Omniscience−2.8
- Terminal-Bench 4.0−3.0
- AutomationBench−6.0
- SciCode−6.9
Qwen 3.8 Max vs DeepSeek V4.1 Flash
Qwen 3.8 Max scores higher than DeepSeek V4.1 Flash in 1 of 8 benchmarks. The widest lead is in Terminal-Bench 4.0: 38.9% against 33.8%. DeepSeek V4.1 Flash is ahead in AutomationBench: 66.6% against 56.2%. Qwen 3.8 Max writes 81 tokens per second, DeepSeek V4.1 Flash writes 422
- Benchmarks won
- Qwen 3.8 Max: 1
- DeepSeek V4.1 Flash: 7
- Average score
- Qwen 3.8 Max: 41.2%
- DeepSeek V4.1 Flash: 44.9%
- Output speed, tokens/s
- Qwen 3.8 Max: 81
- DeepSeek V4.1 Flash: 422
- Time to first token, s (log scale)
- Qwen 3.8 Max: 30.6
- DeepSeek V4.1 Flash: 2.2
- Terminal-Bench 4.0+5.1
- Humanity's Last Exam−0.2
- Terminal-Bench-Science−1.0
- AA-LCR−2.4
- SciCode−3.8
- CritPt−6.3
- AA-Omniscience−10.1
- AutomationBench−10.4
- Terminal-Bench 2.1—
- τ-Bench Banking—
- GPQA Diamond—
Qwen 3.8 Max vs Grok 4.7
Qwen 3.8 Max scores higher than Grok 4.7 in 3 of 8 benchmarks. The widest lead is in Terminal-Bench 4.0: 38.9% against 25.8%. Grok 4.7 is ahead in AA-Omniscience: 42.7% against 29.5%. Qwen 3.8 Max writes 81 tokens per second, Grok 4.7 writes 81
- Benchmarks won
- Qwen 3.8 Max: 3
- Grok 4.7: 5
- Average score
- Qwen 3.8 Max: 41.2%
- Grok 4.7: 42.5%
- Output speed, tokens/s
- Qwen 3.8 Max: 81
- Grok 4.7: 81
- Time to first token, s (log scale)
- Qwen 3.8 Max: 30.6
- Grok 4.7: 8.9
- Terminal-Bench 4.0+13.1
- AA-LCR+3.6
- Terminal-Bench-Science+0.5
- Humanity's Last Exam0.0
- CritPt0.0
- SciCode−5.3
- AutomationBench−9.4
- AA-Omniscience−13.2
- Terminal-Bench 2.1—
- τ-Bench Banking—
- GPQA Diamond—
Best model by use case
Average benchmark scores of Qwen 3.8 Max and 3 other models by use case
Coding
?Average of 3 tests- 1GLM 5.336.8%
- 2Qwen 3.8 Max34.3%
- 3DeepSeek V4.1 Flash34.2%
- 4Grok 4.731.5%
Knowledge work
?Average of 3 tests- 1DeepSeek V4.1 Flash63.0%
- 2Grok 4.761.7%
- 3GLM 5.358.1%
- 4Qwen 3.8 Max55.3%
Reasoning
?Average of 2 tests- 1DeepSeek V4.1 Flash33.6%
- 2GLM 5.330.7%
- 3Qwen 3.8 Max30.4%
- 4Grok 4.730.4%
Qwen 3.8 Max benchmarks
Compare Qwen 3.8 Max with GLM 5.3, DeepSeek V4.1 Flash and Grok 4.7 in 11 benchmarks measuring coding, agents, knowledge work and reasoning
Coding
- Terminal-Bench 4.0?Qwen 3.8 Max38.9%GLM 5.341.9%DeepSeek V4.1 Flash33.8%Grok 4.725.8%38.9%−3.0
- Terminal-Bench 2.1?Qwen 3.8 Max88.8%GLM 5.383.9%DeepSeek V4.1 Flash—Grok 4.7—88.8%+4.9
- SciCode?Qwen 3.8 Max52.1%GLM 5.359.0%DeepSeek V4.1 Flash55.9%Grok 4.757.4%52.1%−6.9
- Terminal-Bench-Science?Qwen 3.8 Max11.9%GLM 5.39.5%DeepSeek V4.1 Flash12.9%Grok 4.711.4%11.9%−1.0
Agents
- τ-Bench Banking?Qwen 3.8 Max47.8%GLM 5.350.3%DeepSeek V4.1 Flash—Grok 4.7—47.8%−2.5
Knowledge work
- AutomationBench?Qwen 3.8 Max56.2%GLM 5.362.2%DeepSeek V4.1 Flash66.6%Grok 4.765.6%56.2%−10.4
- AA-LCR?Qwen 3.8 Max80.3%GLM 5.379.7%DeepSeek V4.1 Flash82.7%Grok 4.776.7%80.3%−2.4
- AA-Omniscience?Qwen 3.8 Max29.5%GLM 5.332.3%DeepSeek V4.1 Flash39.6%Grok 4.742.7%29.5%−13.2
Reasoning
- GPQA Diamond?Qwen 3.8 Max92.8%GLM 5.391.7%DeepSeek V4.1 Flash—Grok 4.7—92.8%+1.1
- Humanity's Last Exam?Qwen 3.8 Max43.1%GLM 5.342.3%DeepSeek V4.1 Flash43.3%Grok 4.743.1%43.1%−0.2
- CritPt?Qwen 3.8 Max17.7%GLM 5.319.1%DeepSeek V4.1 Flash24.0%Grok 4.717.7%17.7%−6.3
Sources: Qwen, Qwen3.8-Max: A New Bar for Coding and Cowork (Aug 3, 2026), Qwen Cloud, model changelog: qwen3.8-max-0902 (Sep 2, 2026), Artificial Analysis, Qwen3.8 Max (0902)
Qwen 3.8 Max speed
Output speed is how fast the model writes (tokens per second, higher is better). Time to first token is how long you wait before the answer starts (lower is better)
Output speed and time to first token of 35 models
?Percentile| Models | Output speed, tokens/s (log scale) | Time to first token, s (log scale) |
|---|---|---|
| GPT-6 Luna | 143 | 2.4 |
| GPT-6.1 Terra | 75 | 4.3 |
| GPT-6.1 Sol | 58 | 2.9 |
| GPT-6 Astra | 48 | 3.2 |
| Claude Opus 5.5 | 88 | 1.9 |
| Claude Opus 5 | 54 | 2.6 |
| Claude Opus 4.8 | 59 | 1.3 |
| Claude Fable 5.2 | 84 | 2.3 |
| Claude Sonnet 5.5 | 102 | 1 |
| Claude 5 Sonnet | 215 | 10.5 |
| Claude Sonnet 4.6 | 220 | 10.8 |
| Claude Haiku 5.5 | 167 | 2.1 |
| Gemini 4 Carbon | 169 | 29.5 |
| Gemini 4 Argon | 91 | 6 |
| Gemini 3.8 Flash | 203 | 7.5 |
| Gemini 3 Pro | 270 | 11.2 |
| Grok 4.7 | 81 | 8.9 |
| Grok 4.6 | 290 | 32 |
| Qwen 3.8 Max | 81 | 30.6 |
| DeepSeek V4 Pro | 144 | 1.1 |
| DeepSeek V4.1 Flash | 422 | 2.2 |
| Mistral Large 4 | 226 | 8.6 |
| Hy4 | 214 | 37.7 |
| ERNIE 5.5 Flash | 405 | 2.7 |
| Muse Wonder | 980 | 8.7 |
| Muse Spark | 1129 | 6.2 |
| Kimi K3.1 Pro | 340 | 7.4 |
| Kimi K3 | 338 | 5.9 |
| GLM 5.3 | 197 | 1.2 |
| Flint | 194 | 12.3 |
| Llama 4 | 81 | 0.7 |
| Claude 4.5 Haiku | 162 | 0.9 |
| MiniMax M3 | 169 | 4.5 |
| MiniMax M3.1 Flash | 656 | 7.2 |
| Kimi K2.7 Code | 455 | 3.6 |
Typing test
Every model writes the same answer. The test waits the model's time to first token, then prints the text at the model's output speed and shows the total time
- Qwen 3.8 Max81 tokens/s30.6 s to first token
- GLM 5.3197 tokens/s1.2 s to first token
- DeepSeek V4.1 Flash422 tokens/s2.2 s to first token
- Grok 4.781 tokens/s8.9 s to first token
Source: Overchat AI, 2026-11-11
See how Qwen 3.8 Max answers
Examples of Qwen 3.8 Max answers to 3 prompts: Build a pricing page, Solve a physics problem and Translate a message. Each answer is the unedited output of the model
Build a single HTML file with a pricing section of three plans and a Monthly / Yearly switch that changes the prices. Use plain CSS and a few lines of JavaScript, no libraries, under 120 lines.
Qwen 3.8 Max<!doctype html>
<html lang="en">
<head>
<meta charset="utf-8">
<meta name="viewport" content="width=device-width, initial-scale=1">
<title>Pricing</title>
<style>
body { margin:0; font-family:system-ui,sans-serif; background:#f6f8fb; color:#111; }
main { max-width:900px; margin:4rem auto; padding:0 1rem; text-align:center; }
h1 { margin:0 0 .5rem; }
.toggle { display:inline-flex; align-items:center; gap:.5rem; margin:1rem 0 2rem; }
.plans { display:grid; grid-template-columns:repeat(auto-fit,minmax(220px,1fr)); gap:1rem; }
.plan { background:#fff; border:1px solid #e5e7eb; border-radius:12px; padding:1.5rem; box-shadow:0 10px 25px rgba(0,0,0,.05); }
.plan.popular { outline:2px solid #4f46e5; transform:scale(1.02); }
.plan h2 { margin:.2rem 0; font-size:1.1rem; }
.price { margin:1rem 0; font-size:2rem; font-weight:700; }
.period { font-size:1rem; color:#6b7280; font-weight:400; }
ul { list-style:none; padding:0; margin:0 0 1.25rem; color:#374151; }
li { margin:.4rem 0; }
button { width:100%; padding:.65rem; border:0; border-radius:8px; background:#111; color:#fff; font-weight:600; cursor:pointer; }
.plan.popular button { background:#4f46e5; }
</style>
</head>
<body>
<main>
<h1>Choose a plan</h1>
<p>Simple pricing. Cancel anytime.</p>
<label class="toggle">
Monthly
<input id="billing" type="checkbox">
Yearly
</label>
<section class="plans">
<article class="plan">
<h2>Starter</h2>
<div class="price"><span class="amount" data-monthly="$9" data-yearly="$90">$9</span><span class="period">/mo</span></div>
<ul>
<li>1 project</li>
<li>Community support</li>
<li>Basic analytics</li>
</ul>
<button>Get Starter</button>
</article>
<article class="plan popular">
<h2>Pro</h2>
<div class="price"><span class="amount" data-monthly="$19" data-yearly="$190">$19</span><span class="period">/mo</span></div>
<ul>
<li>10 projects</li>
<li>Priority support</li>
<li>Advanced analytics</li>
</ul>
<button>Get Pro</button>
</article>
<article class="plan">
<h2>Business</h2>
<div class="price"><span class="amount" data-monthly="$39" data-yearly="$390">$39</span><span class="period">/mo</span></div>
<ul>
<li>Unlimited projects</li>
<li>Dedicated support</li>
<li>SSO and audit logs</li>
</ul>
<button>Get Business</button>
</article>
</section>
</main>
<script>
const toggle = document.getElementById("billing");
function update() {
const yearly = toggle.checked;
document.querySelectorAll(".amount").forEach(el => {
el.textContent = yearly ? el.dataset.yearly : el.dataset.monthly;
});
document.querySelectorAll(".period").forEach(el => {
el.textContent = yearly ? "/yr" : "/mo";
});
}
toggle.addEventListener("change", update);
</script>
</body>
</html>A ball is kicked from the ground at 20 m/s at 35° above the horizontal. Ignoring air resistance, how high does it go, how long is it in the air and how far does it land? Show the steps briefly with g = 9.81 m/s². Write the math as plain text, not LaTeX.
Qwen 3.8 MaxGiven:
- Initial speed: v = 20 m/s
- Launch angle: theta = 35 degrees
- g = 9.81 m/s^2
- Assume it lands at the same height it was kicked from.
Velocity components:
vx = 20 cos(35) = 16.38 m/s
vy = 20 sin(35) = 11.47 m/s
- Maximum height
At the highest point, vertical velocity is 0.
0 = vy^2 - 2 g h
h = vy^2 / (2g)
h = (11.47)^2 / (2 * 9.81)
h = 131.6 / 19.62
h = 6.71 m
- Time in the air
Time to reach the top:
t_up = vy / g
t_up = 11.47 / 9.81
t_up = 1.17 s
Total time:
t_total = 2 t_up
t_total = 2 * 1.17
t_total = 2.34 s
- Horizontal distance
range = vx * t_total
range = 16.38 * 2.34
range = 38.3 m
Final answers:
- Maximum height: 6.71 m
- Time in the air: 2.34 s
- Landing distance: 38.3 m
Translate this message to a customer into Spanish, German and Japanese, keeping the friendly, polite tone: "Thanks for your order! It ships tomorrow and should reach you by Friday. If anything is wrong with it, just reply to this email and we'll fix it."
Qwen 3.8 MaxSpanish
¡Gracias por su pedido! Se enviará mañana y debería llegarle el viernes. Si algo no está bien, simplemente responda a este correo y lo solucionaremos.
German
Vielen Dank für Ihre Bestellung! Sie wird morgen versendet und sollte Sie bis Freitag erreichen. Falls etwas nicht in Ordnung ist, antworten Sie einfach auf diese E-Mail, und wir kümmern uns darum.
Japanese
ご注文ありがとうございます!商品は明日発送され、金曜日までに届く予定です。もし何か問題がございましたら、このメールにご返信いただければ、対応いたします。
More prompts to try with Qwen 3.8 Max
What Qwen 3.8 Max is best for
Websites and apps
Qwen 3.8 Max writes front-end code, whole pages and small apps from a plain request, and fixes them in the same chat. It scores 88.8% on Terminal-Bench 2.1, fifth among 140 models
Math and science
Qwen 3.8 Max solves physics, chemistry and math problems step by step, with 92.8% on GPQA Diamond, a test of graduate-level science questions
Writing in many languages
Qwen 3.8 Max writes, edits and translates in English, Chinese, Spanish, Japanese and dozens of other languages, and keeps the tone of the original
Long documents
Qwen 3.8 Max reads up to 1 million tokens at once, about 1,500 pages, and answers questions across a whole report, contract or codebase, with 80.3% on AA-LCR
How to use Qwen 3.8 Max on Overchat AI
Start in the chat at the top of this page or in the Overchat AI app on the web, iOS or Android
- 01
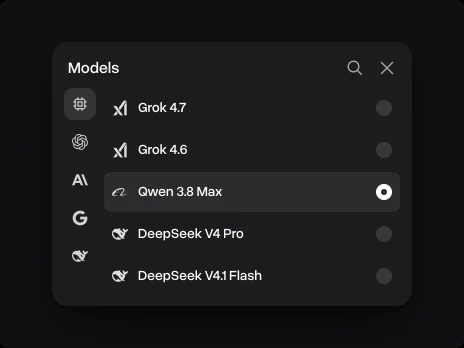
Pick Qwen 3.8 Max
It is already picked in the chat on this page. In the Overchat AI app, open the model list next to the message field and pick Qwen 3.8 Max
- 02
Write your request
Paste your text or code and write what you need: the result, the format and what must stay the same
- 03
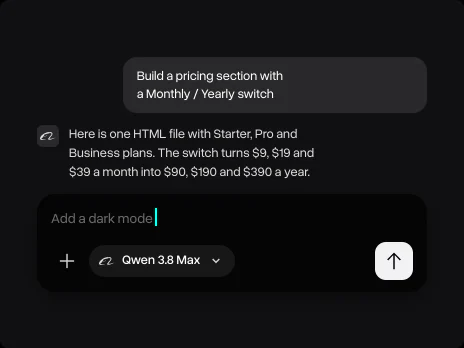
Keep going in the same chat
Ask a follow-up, ask for tests or a shorter version, or switch to another model without losing the conversation
Why use Qwen 3.8 Max on Overchat AI
One account for chat, images and video, on every device
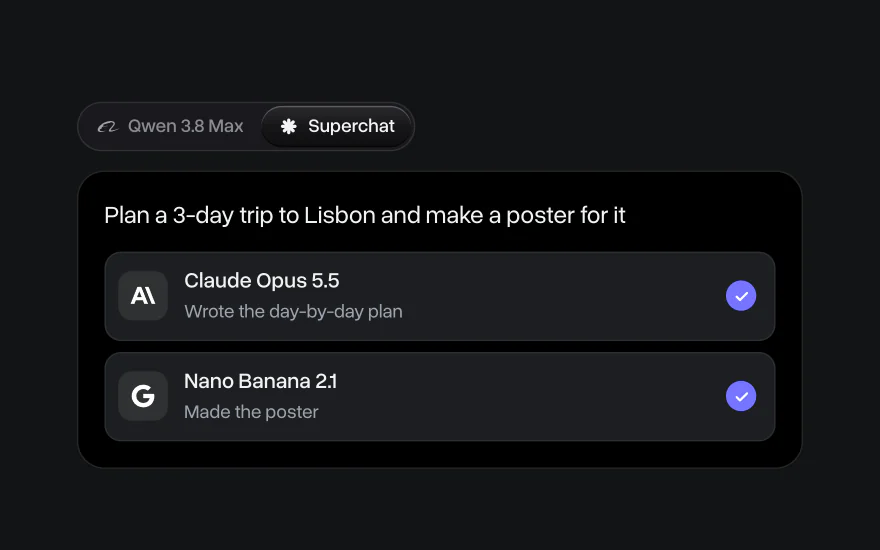
Superchat AI agent
Superchat Agent automatically routes your message to the model best suited for the task. It can generate images and videos, use the AI tools built into Overchat AI, and learn from your interactions to get better over time
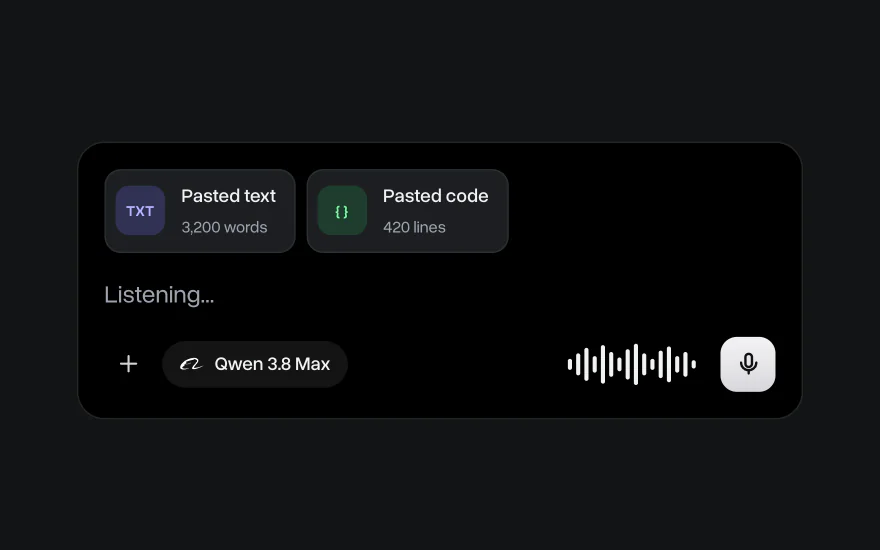
Paste long texts and code
Paste a long document, a log or a whole file of code and ask Qwen 3.8 Max about it. You can also dictate a message instead of typing it
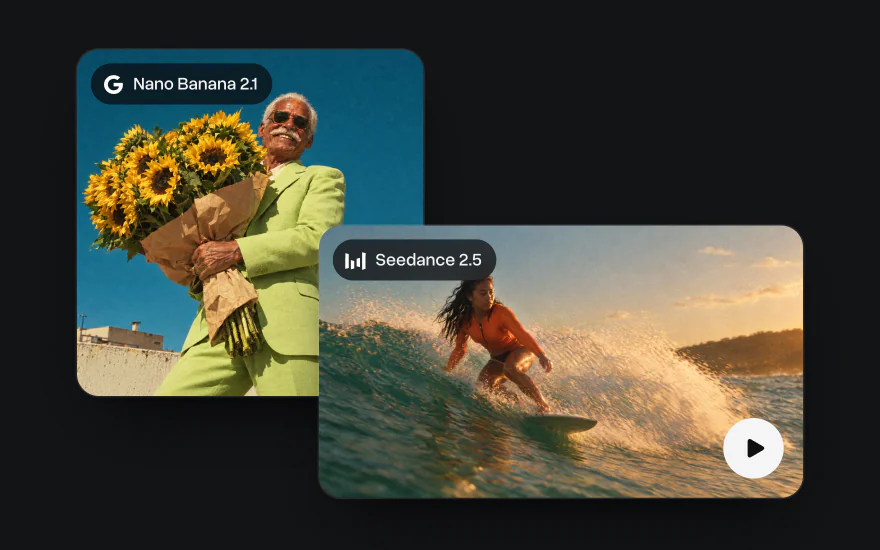
Go beyond text
Generate images with Nano Banana and GPT Image and videos with Seedance and Kling in the same account, with the same credits as chat
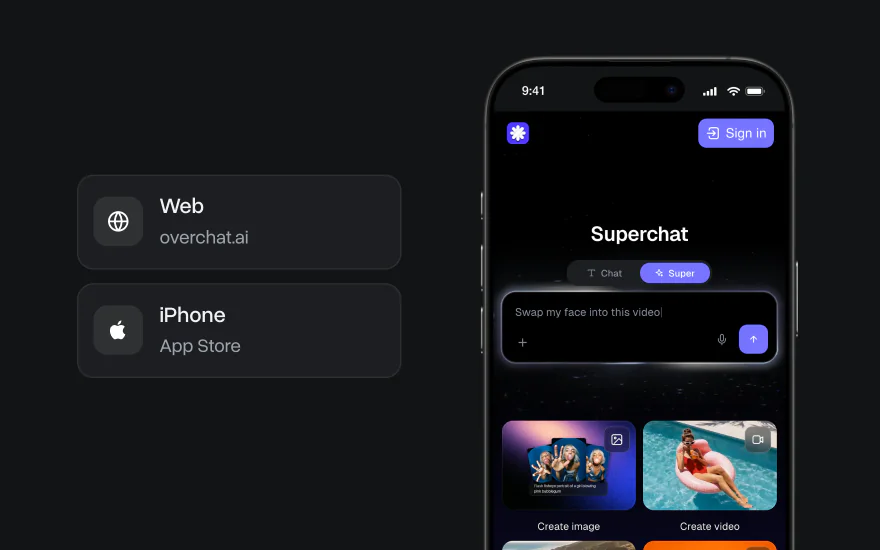
On the web and iPhone
Start a chat on your laptop and finish it on your phone. The Overchat AI app has the same models, and your chats stay in one account on every device
Explore other models
Models marked Soon are coming to Overchat AI; the rest are available now


Learn more about AI models

We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder
We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder on three coding tasks. See benchmarks, speed and how to use it
Muse Wonder vs Muse Spark: Meta's New Model Tested
We tested Muse Wonder against Muse Spark 1.3 on logic, writing and coding tasks. See benchmarks and which Meta model is better
10 Best All-in-One AI Platforms in 2026: Why One AI Subscription Beats Many
Compare the 10 best all-in-one AI platforms in 2026, from Overchat AI to Poe and Magai, with prices, free plans and the newest GPT and Claude models



