


About DeepSeek V4.1 Flash
DeepSeek V4.1 Flash is DeepSeek's open model for coding agents, business automation and questions about images. It has 552 billion parameters, of which 8 billion work on each token while it reads and 16 billion while it writes, and it holds up to 1 million tokens in one conversation
The October 17 update of DeepSeek V4.1 Flash scores 77.0% on DeepSWE v1.1, ahead of Claude Opus 5 at 74.0%, and 60.5% on AutomationBench against 50.3% for Opus 5. It reads screenshots, charts and photos on its own, and DeepSeek moved the traffic of its bigger V4 Pro model to it
On Overchat AI, you can ask DeepSeek V4.1 Flash, attach a photo or a file and switch to Claude or GPT-6 in the same conversation
- Modalities
- Intelligence Index?
- 33
- Context window?
- 1M tokens
- Released
- Oct 17, 2026
DeepSeek V4.1 Flash vs other models
DeepSeek V4.1 Flash ranks #17 on the Artificial Analysis Intelligence Index out of 54 models
- 59
 Claude Opus 5.5
- 46
 Kimi K3.1 Pro
- 36Claude Haiku 5.5
- 35
 Grok 4.7
- 35
 Hy4
- 34
 Qwen 3.8 Max
- 33
 DeepSeek V4.1 Flash
- 32
 GLM 5.3
- 31
 Gemini 3.8 Flash
- 29
 MiniMax M3.1 Flash
- #9of 100 modelsAutomationBenchBusiness workflows an agent runs across many apps
- #12of 37 modelsFrontierCodeCode changes an agent writes, graded on whether they are ready to merge
- #13of 77 modelsMMMU ProCollege-level questions about charts, diagrams and photos
- #15of 187 modelsCritPtResearch-level physics problems
Source: Artificial Analysis
Compare DeepSeek V4.1 Flash
DeepSeek V4.1 Flash vs Claude Opus 5
DeepSeek V4.1 Flash scores higher than Claude Opus 5 in 3 of 9 benchmarks. The widest lead is in AutomationBench: 60.5% against 50.3%. Claude Opus 5 is ahead in Terminal-Bench 4.0: 51.8% against 42.3%. DeepSeek V4.1 Flash writes 422 tokens per second, Claude Opus 5 writes 54
- Benchmarks won
- DeepSeek V4.1 Flash: 3
- Claude Opus 5: 6
- Average score
- DeepSeek V4.1 Flash: 64.0%
- Claude Opus 5: 64.9%
- Output speed, tokens/s
- DeepSeek V4.1 Flash: 422
- Claude Opus 5: 54
- Time to first token, s (log scale)
- DeepSeek V4.1 Flash: 2.2
- Claude Opus 5: 2.6
- AutomationBench+10.2
- APEX-Agents 1.1+6.3
- DeepSWE v1.1+3.0
- Chartography−1.0
- ZeroBench−1.0
- BabyVision−1.6
- NL2Repo-Bench−7.1
- ProgramBench−7.9
- Terminal-Bench 4.0−9.5
DeepSeek V4.1 Flash vs Kimi K3
DeepSeek V4.1 Flash scores higher than Kimi K3 in 9 of 9 benchmarks. The widest lead is in Terminal-Bench 4.0: 42.3% against 12.6%. DeepSeek V4.1 Flash writes 422 tokens per second, Kimi K3 writes 338
- Benchmarks won
- DeepSeek V4.1 Flash: 9
- Kimi K3: 0
- Average score
- DeepSeek V4.1 Flash: 64.0%
- Kimi K3: 49.4%
- Output speed, tokens/s
- DeepSeek V4.1 Flash: 422
- Kimi K3: 338
- Time to first token, s (log scale)
- DeepSeek V4.1 Flash: 2.2
- Kimi K3: 5.9
- Terminal-Bench 4.0+29.7
- APEX-Agents 1.1+24.3
- Chartography+14.9
- AutomationBench+13.8
- ProgramBench+11.6
- NL2Repo-Bench+10.2
- ZeroBench+10.0
- DeepSWE v1.1+9.5
- BabyVision+6.8
DeepSeek V4.1 Flash vs GLM 5.3
DeepSeek V4.1 Flash scores higher than GLM 5.3 in 6 of 6 benchmarks. The widest lead is in APEX-Agents 1.1: 72.1% against 56.6%. DeepSeek V4.1 Flash writes 422 tokens per second, GLM 5.3 writes 197
- Benchmarks won
- DeepSeek V4.1 Flash: 6
- GLM 5.3: 0
- Average score
- DeepSeek V4.1 Flash: 58.2%
- GLM 5.3: 47.9%
- Output speed, tokens/s
- DeepSeek V4.1 Flash: 422
- GLM 5.3: 197
- Time to first token, s (log scale)
- DeepSeek V4.1 Flash: 2.2
- GLM 5.3: 1.2
- APEX-Agents 1.1+15.5
- AutomationBench+11.7
- NL2Repo-Bench+10.2
- DeepSWE v1.1+10.1
- ProgramBench+10.1
- Terminal-Bench 4.0+4.4
- Chartography—
- BabyVision—
- ZeroBench—
Best model by use case
Average benchmark scores of DeepSeek V4.1 Flash and 3 other models by use case
Coding
?Average of 4 tests- 1Claude Opus 559.5%
- 2DeepSeek V4.1 Flash54.2%
- 3GLM 5.345.5%
- 4Kimi K338.9%
Agents
?AutomationBench- 1DeepSeek V4.1 Flash60.5%
- 2Claude Opus 550.3%
- 3GLM 5.348.8%
- 4Kimi K346.7%
Knowledge work
?APEX-Agents 1.1- 1DeepSeek V4.1 Flash72.1%
- 2Claude Opus 565.8%
- 3GLM 5.356.6%
- 4Kimi K347.8%
DeepSeek V4.1 Flash benchmarks
Compare DeepSeek V4.1 Flash with Claude Opus 5, Kimi K3 and GLM 5.3 in 9 benchmarks measuring coding, agents and knowledge work
Coding
- Terminal-Bench 4.0?DeepSeek V4.1 Flash42.3%Claude Opus 551.8%Kimi K312.6%GLM 5.337.9%42.3%−9.5
- DeepSWE v1.1?DeepSeek V4.1 Flash77.0%Claude Opus 574.0%Kimi K367.5%GLM 5.366.9%77.0%+3.0
- ProgramBench?DeepSeek V4.1 Flash29.1%Claude Opus 537.0%Kimi K317.5%GLM 5.319.0%29.1%−7.9
- NL2Repo-Bench?DeepSeek V4.1 Flash68.2%Claude Opus 575.3%Kimi K358.0%GLM 5.358.0%68.2%−7.1
Agents
- AutomationBench?DeepSeek V4.1 Flash60.5%Claude Opus 550.3%Kimi K346.7%GLM 5.348.8%60.5%+10.2
- Chartography?DeepSeek V4.1 Flash83.0%Claude Opus 584.0%Kimi K368.1%GLM 5.3—83.0%−1.0
- BabyVision?DeepSeek V4.1 Flash92.5%Claude Opus 594.1%Kimi K385.7%GLM 5.3—92.5%−1.6
- ZeroBench?DeepSeek V4.1 Flash51.0%Claude Opus 552.0%Kimi K341.0%GLM 5.3—51.0%−1.0
Knowledge work
- APEX-Agents 1.1?DeepSeek V4.1 Flash72.1%Claude Opus 565.8%Kimi K347.8%GLM 5.356.6%72.1%+6.3
Sources: DeepSeek, DeepSeek-V4.1-Flash-1017 model card (Oct 17, 2026), DeepSeek, DeepSeek-V4.1-Flash model card (Sep 10, 2026)
DeepSeek V4.1 Flash speed
Output speed is how fast the model writes (tokens per second, higher is better). Time to first token is how long you wait before the answer starts (lower is better)
Output speed and time to first token of 35 models
?Percentile| Models | Output speed, tokens/s (log scale) | Time to first token, s (log scale) |
|---|---|---|
| GPT-6 Luna | 143 | 2.4 |
| GPT-6.1 Terra | 75 | 4.3 |
| GPT-6.1 Sol | 58 | 2.9 |
| GPT-6 Astra | 48 | 3.2 |
| Claude Opus 5.5 | 88 | 1.9 |
| Claude Opus 5 | 54 | 2.6 |
| Claude Opus 4.8 | 59 | 1.3 |
| Claude Fable 5.2 | 84 | 2.3 |
| Claude Sonnet 5.5 | 102 | 1 |
| Claude 5 Sonnet | 215 | 10.5 |
| Claude Sonnet 4.6 | 220 | 10.8 |
| Claude Haiku 5.5 | 167 | 2.1 |
| Gemini 4 Carbon | 169 | 29.5 |
| Gemini 4 Argon | 91 | 6 |
| Gemini 3.8 Flash | 203 | 7.5 |
| Gemini 3 Pro | 270 | 11.2 |
| Grok 4.7 | 81 | 8.9 |
| Grok 4.6 | 290 | 32 |
| Qwen 3.8 Max | 81 | 30.6 |
| DeepSeek V4 Pro | 144 | 1.1 |
| DeepSeek V4.1 Flash | 422 | 2.2 |
| Mistral Large 4 | 226 | 8.6 |
| Hy4 | 214 | 37.7 |
| ERNIE 5.5 Flash | 405 | 2.7 |
| Muse Wonder | 980 | 8.7 |
| Muse Spark | 1129 | 6.2 |
| Kimi K3.1 Pro | 340 | 7.4 |
| Kimi K3 | 338 | 5.9 |
| GLM 5.3 | 197 | 1.2 |
| Flint | 194 | 12.3 |
| Llama 4 | 81 | 0.7 |
| Claude 4.5 Haiku | 162 | 0.9 |
| MiniMax M3 | 169 | 4.5 |
| MiniMax M3.1 Flash | 656 | 7.2 |
| Kimi K2.7 Code | 455 | 3.6 |
Typing test
Every model writes the same answer. The test waits the model's time to first token, then prints the text at the model's output speed and shows the total time
- DeepSeek V4.1 Flash422 tokens/s2.2 s to first token
- Claude Opus 554 tokens/s2.6 s to first token
- Kimi K3338 tokens/s5.9 s to first token
- GLM 5.3197 tokens/s1.2 s to first token
Source: Overchat AI, 2026-11-11
See how DeepSeek V4.1 Flash answers
Examples of DeepSeek V4.1 Flash answers to 3 prompts: Rename my photos, Solve a math puzzle and Write a client proposal. Each answer is the unedited output of the model
Write a Python script that watches a folder and renames each new photo by the date it was taken (from its EXIF data), like 2026-11-11_14-03-22.jpg. Keep it short and list the packages to install.
DeepSeek V4.1 Flashimport time
from datetime import datetime
from pathlib import Path
from PIL import Image
from watchdog.events import FileSystemEventHandler
from watchdog.observers import Observer
WATCH = Path("./photos")
EXTS = {".jpg", ".jpeg", ".png", ".tif", ".tiff", ".webp"}
def exif_datetime(path):
"""Return the EXIF capture datetime, or None."""
try:
with Image.open(path) as im:
exif = im.getexif()
ifd = exif.get_ifd(0x8769) # Exif sub-IFD
raw = ifd.get(36867) or ifd.get(36868) or exif.get(306) # Original / Digitized / DateTime
if not raw:
return None
for fmt in ("%Y:%m:%d %H:%M:%S", "%Y-%m-%d %H:%M:%S"):
try:
return datetime.strptime(raw.strip(), fmt)
except ValueError:
pass
except Exception:
return None
def rename(path: Path):
if path.suffix.lower() not in EXTS:
return
# Retry: the file may still be being written when the event fires.
dt = None
for _ in range(10):
dt = exif_datetime(path)
if dt or not path.exists():
break
time.sleep(0.5)
if not dt:
print(f"skipped (no EXIF date): {path.name}")
return
stamp = dt.strftime("%Y-%m-%d_%H-%M-%S")
target = path.with_name(f"{stamp}{path.suffix.lower()}")
n = 1
while target.exists() and target != path:
target = path.with_name(f"{stamp}_{n}{path.suffix.lower()}")
n += 1
if target == path:
return
path.rename(target)
print(f"{path.name} -> {target.name}")
class Handler(FileSystemEventHandler):
def on_created(self, event):
if not event.is_directory:
rename(Path(event.src_path))
def on_moved(self, event):
if not event.is_directory:
rename(Path(event.dest_path))
if __name__ == "__main__":
WATCH.mkdir(parents=True, exist_ok=True)
for p in WATCH.iterdir(): # handle files already there
if p.is_file():
rename(p)
observer = Observer()
observer.schedule(Handler(), str(WATCH), recursive=False)
observer.start()
print(f"watching {WATCH.resolve()} (Ctrl+C to stop)")
try:
while True:
time.sleep(1)
except KeyboardInterrupt:
observer.stop()
observer.join()Install
pip install Pillow watchdogNotes:
- Falls back gracefully: files without EXIF are left alone and logged.
- Collisions get
_1,_2, … appended. .heicisn't supported by Pillow out of the box — addpillow-heifandpillow_heif.register_heif_opener()if you need it.on_movedis included so photos dragged into the folder are caught too (on macOSon_createdfires for those, on Linux it's a move event).
Pens come in packs of 7 and packs of 11. What is the largest number of pens you can't buy exactly? Explain the answer in a few lines.
DeepSeek V4.1 FlashThe largest number you can’t buy exactly is 59.
Since 7 and 11 are coprime, the Frobenius coin problem gives:
7 × 11 − 7 − 11 = 77 − 18 = 59
So any amount greater than 59 can be made with packs of 7 and 11, but 59 cannot be made exactly.
I'm a freelance designer. Write a one-page proposal for a café that wants a new logo and menu: the scope, a 3-week timeline, three price packages and what I need from the client to start.
DeepSeek V4.1 FlashLogo & Menu Design — Proposal
Prepared for: [Café Name] · Prepared by: [Your Name], Independent Designer · Date: [Date]
The Short Version
Your logo needs to work at 3 cm on a sugar packet and 3 m on a window. Your menu needs to be readable at 8 a.m. in bad lighting and priced so it doesn't get reprinted every season. This project delivers both — a small, flexible identity and a menu system you can update yourself, designed and print-ready in three weeks.
Scope of Work
Logo & identity
- Discovery call + short written brief (positioning, audience, tone)
- Up to 3 logo directions, one round of refinement on your chosen route
- Wordmark + stacked + icon-only lockups
- Colour palette, 2 typefaces, and a one-page usage guide (clear space, minimum size, don't-dos)
- Deliverables: vector (AI/SVG), PNG, PDF — colour, mono, and reversed for dark backgrounds
Menu
- One primary menu (food, drinks, or combined) plus one secondary — e.g. counter card, drinks list, or daily specials template
- Layout, type hierarchy, and pricing grid designed for easy in-house edits
- Print-ready PDFs with bleed and crop marks; editable working file included
- Photo placeholders noted so you can drop in imagery later
Timeline — 3 Weeks
| Focus | You receive / you do | |
|---|---|---|
| Week 1 | Kickoff, brief, moodboard, logo concepts | Discovery call (45 min); 2–3 directions by Friday |
| Week 2 | Logo refinement, menu layout first draft | One consolidated feedback round (by Tuesday); full menu draft by Friday |
| Week 3 | Menu revisions, prepress, handoff | Final proof Wednesday; complete files Friday |
Each stage depends on the previous one landing on time — the single biggest delay factor is consolidated feedback.
Three Packages
| Essential — $1,450 | Signature — $2,400 | Full Service — $3,800 | |
|---|---|---|---|
| Logo directions | 2 | 3 | 3 + custom illustration/lettering |
| Refinement rounds | 1 | 2 | 3 |
| Menu designs | 1 menu | 2 menus + editable template | 3 menus, seasonal template, chalkboard/counter set |
| Brand guide | 1 page | 3 pages | 8–10 page mini-guide |
| Copy help | — | Menu editing for clarity | Full menu copywriting + pricing structure advice |
| Extras | — | Social profile kit (avatar, cover, 3 post templates) | Print liaison + press check, packaging stamp/label |
| Timeline | 2.5 weeks | 3 weeks | 3 weeks (expedited possible) |
All packages include: source files, print-ready PDFs, full ownership of final artwork, and 30 days of post-handoff support. Payment: 50% to book, 50% on delivery. Additional rounds billed at $95/hr; extra menus $300 each.
What I Need From You to Start
- Confirmed package + 50% deposit — this books your dates
- A single decision-maker who can approve work on behalf of the café
- Copy for the menu — item names, descriptions, prices (or add copywriting to your package)
- Brand inputs — existing logo/files, anything you love or hate visually, 3 competitor cafés you admire and why
- Practical specs — menu trim size, print vendor if chosen, and any dietary/allergen or legally required text
- Photos or a plan for them — current images or a placeholder decision
- Feedback in one voice — one collated round per stage, within 2 business days
Not Included
Printing and production costs, professional photography, copy translation, and trademark registration searches (I can recommend a service for the last one).
Next Step
Reply confirming your package and I'll send the agreement and deposit invoice within 24 hours, with kickoff booked for the first available slot.
[your email] · [your phone] · [portfolio link]
More prompts to try with DeepSeek V4.1 Flash
What DeepSeek V4.1 Flash is best for
Coding agents
DeepSeek V4.1 Flash solves 77.0% of the real software tasks in DeepSWE v1.1, more than Claude Opus 5, and writes whole repositories from a description, with 68.2% on NL2Repo-Bench
Business automation
DeepSeek V4.1 Flash runs workflows across sales, support, finance and HR apps, with 60.5% on AutomationBench, the top score among the models it is compared with
Questions about images
DeepSeek V4.1 Flash reads screenshots, charts and photos on its own. It scores 92.5% on BabyVision and 83.0% on Chartography, close to Claude Opus 5
Math and contest problems
DeepSeek V4.1 Flash has a Codeforces rating of 3,471 and scores 65.6% on MathArena Apex, so it handles olympiad math and competitive programming
How to use DeepSeek V4.1 Flash on Overchat AI
Start in the chat at the top of this page or in the Overchat AI app on the web, iOS or Android
- 01
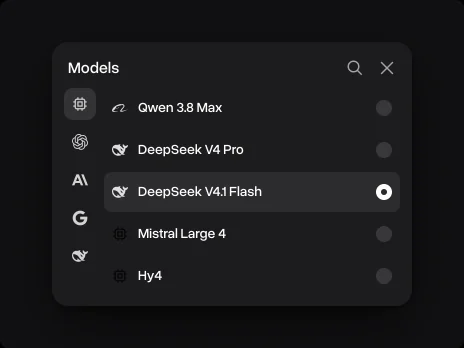
Pick DeepSeek V4.1 Flash
It is already picked in the chat on this page. In the Overchat AI app, open the model list next to the message field and pick DeepSeek V4.1 Flash
- 02
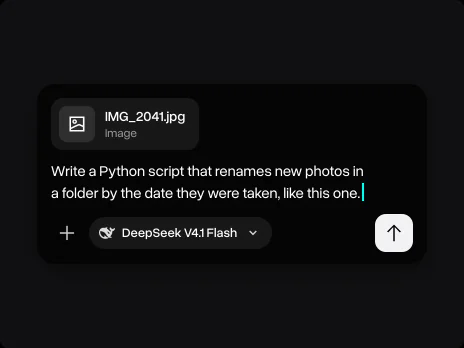
Attach your code or a file
Add code, a document, a spreadsheet or a screenshot, and write what you need: the result, the format and what must stay the same
- 03
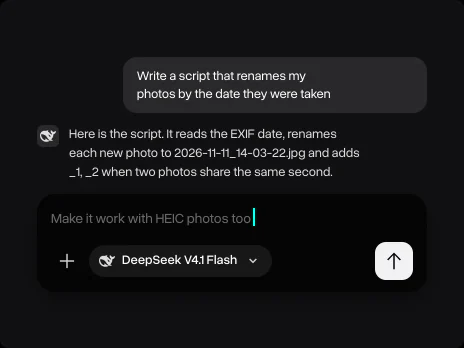
Keep going in the same chat
Ask a follow-up, ask for tests or a shorter version, or switch to another model without losing the conversation
Why use DeepSeek V4.1 Flash on Overchat AI
One account for chat, images and video, on every device
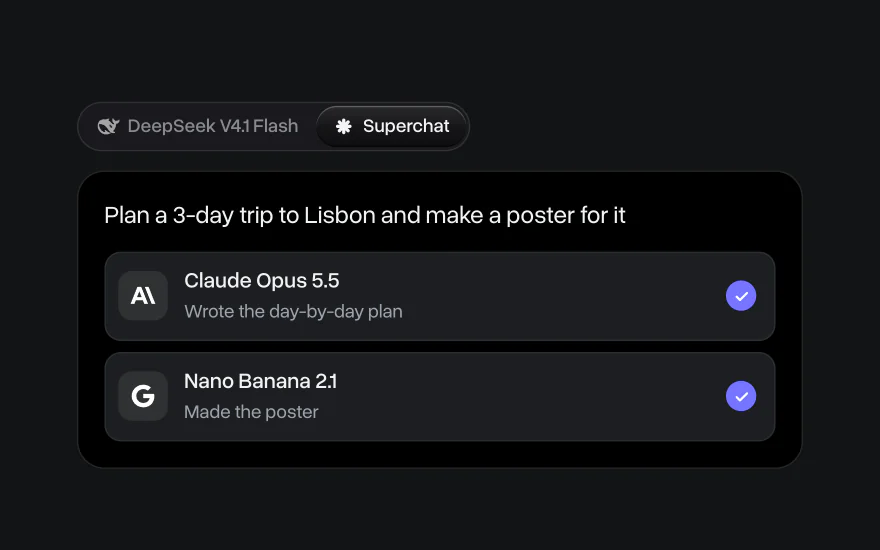
Superchat AI agent
Superchat Agent automatically routes your message to the model best suited for the task. It can generate images and videos, use the AI tools built into Overchat AI, and learn from your interactions to get better over time
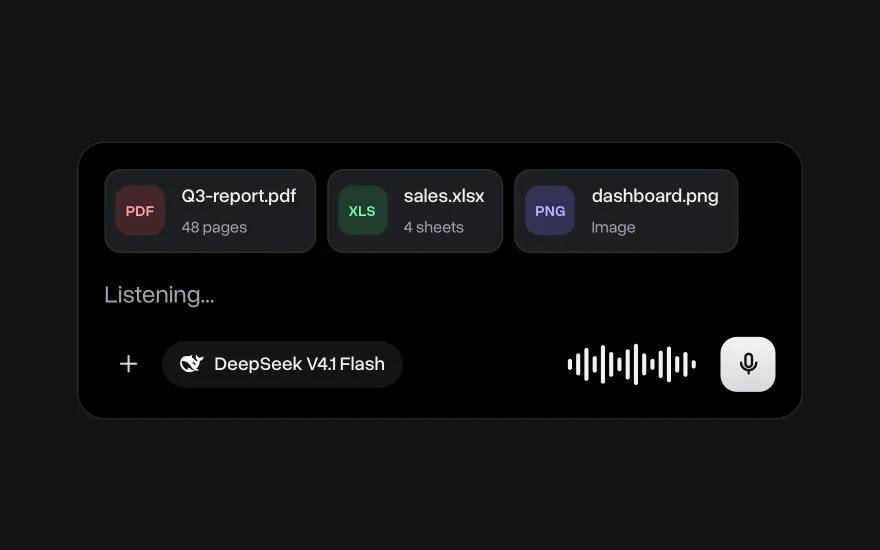
Chat with images and files
Upload PDFs, spreadsheets, code and screenshots and ask DeepSeek V4.1 Flash about them. You can also dictate a message instead of typing it
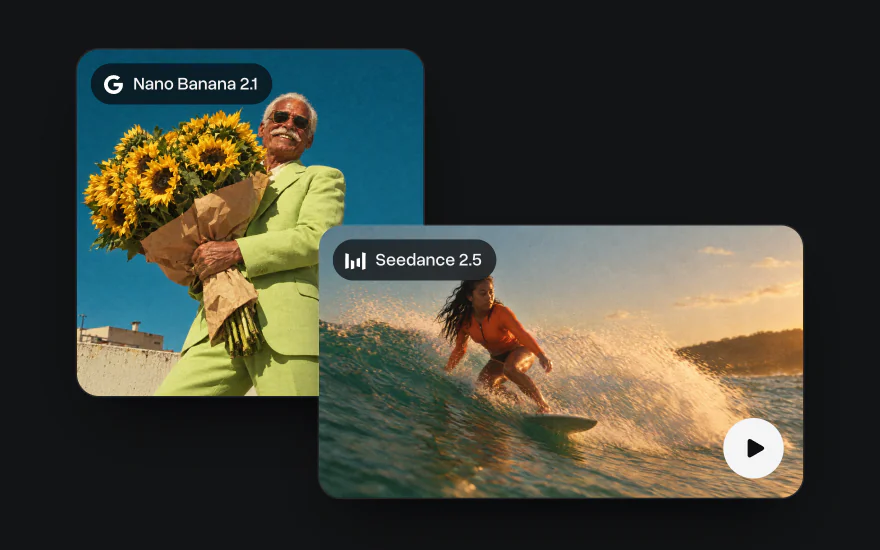
Go beyond text
Generate images with Nano Banana and GPT Image and videos with Seedance and Kling in the same account, with the same credits as chat
On the web and iPhone
Start a chat on your laptop and finish it on your phone. The Overchat AI app has the same models, and your chats stay in one account on every device
DeepSeek models on Overchat AI
Compare 2 DeepSeek models on Overchat AI by output speed, time to first token and the price of one message
DeepSeek V4 ProDeepSeek V4.1 FlashThis pageSource: Overchat AI, 2026-11-11
Explore other models
Models marked Soon are coming to Overchat AI; the rest are available now


Learn more about AI models

We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder
We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder on three coding tasks. See benchmarks, speed and how to use it
Muse Wonder vs Muse Spark: Meta's New Model Tested
We tested Muse Wonder against Muse Spark 1.3 on logic, writing and coding tasks. See benchmarks and which Meta model is better
10 Best All-in-One AI Platforms in 2026: Why One AI Subscription Beats Many
Compare the 10 best all-in-one AI platforms in 2026, from Overchat AI to Poe and Magai, with prices, free plans and the newest GPT and Claude models



