


About GPT-6 Luna
GPT-6 Luna is the smallest and fastest model of OpenAI's GPT-6 family, below GPT-6.1 Terra, GPT-6.1 Sol and GPT-6 Astra. It reads text, images and files, holds about 1 million tokens in one conversation and writes up to 128,000 tokens in one answer
GPT-6 Luna solves 66.6% of the real software tasks in DeepSWE v1.1, close to Claude Opus 5 at medium effort, and makes 37% fewer factual mistakes than GPT-5.6 Luna. It scores 83.3% on AA-LCR, the best result among the models it is compared with at reading very long documents
GPT-6 Luna is free on Overchat AI: a free account gets 100 credits every day with no card, and a GPT-6 Luna message takes 3 of them. In the same chat you can switch to Claude, Gemini or DeepSeek
- Modalities
- Intelligence Index?
- 28
- Context window?
- 1M tokens
- Released
- Sep 22, 2026
GPT-6 Luna vs other models
GPT-6 Luna ranks #25 on the Artificial Analysis Intelligence Index out of 54 models
- 57
 GPT-6 Astra
- 55GPT-6.1 Sol
- 51GPT-6.1 Terra
- 36
 Claude Haiku 5.5
- 35
 Grok 4.7
- 33
 DeepSeek V4.1 Flash
- 31
 Gemini 3.8 Flash
- 29
 MiniMax M3.1 Flash
- 28GPT-6 Luna
- 23DeepSeek V4 Pro
- #9of 183 modelsAA-LCRQuestions that need reasoning over very long documents
- #15of 77 modelsMMMU ProCollege-level questions about charts, diagrams and photos
- #16of 37 modelsFrontierCodeCode changes an agent writes, graded on whether they are ready to merge
- #20of 187 modelsCritPtResearch-level physics problems
Source: Artificial Analysis
Compare GPT-6 Luna
GPT-6 Luna vs GPT-6.1 Terra
GPT-6 Luna scores higher than GPT-6.1 Terra in 2 of 8 benchmarks. The widest lead is in FrontierCode: 41.9% against 36.0%. GPT-6.1 Terra is ahead in Terminal-Bench 4.0: 55.6% against 12.6%. GPT-6 Luna writes 143 tokens per second, GPT-6.1 Terra writes 75
- Benchmarks won
- GPT-6 Luna: 2
- GPT-6.1 Terra: 6
- Average score
- GPT-6 Luna: 42.9%
- GPT-6.1 Terra: 51.4%
- Output speed, tokens/s
- GPT-6 Luna: 143
- GPT-6.1 Terra: 75
- Time to first token, s (log scale)
- GPT-6 Luna: 2.4
- GPT-6.1 Terra: 4.3
- FrontierCode+5.9
- AA-LCR+0.6
- SciCode−0.5
- AutomationBench−7.0
- Humanity's Last Exam−7.7
- AA-Omniscience−8.0
- CritPt−8.6
- Terminal-Bench 4.0−43.0
GPT-6 Luna vs Claude Haiku 5.5
GPT-6 Luna scores higher than Claude Haiku 5.5 in 5 of 8 benchmarks. The widest lead is in AutomationBench: 53.2% against 35.4%. Claude Haiku 5.5 is ahead in Terminal-Bench 4.0: 32.8% against 12.6%. GPT-6 Luna writes 143 tokens per second, Claude Haiku 5.5 writes 167
- Benchmarks won
- GPT-6 Luna: 5
- Claude Haiku 5.5: 3
- Average score
- GPT-6 Luna: 42.9%
- Claude Haiku 5.5: 43.2%
- Output speed, tokens/s
- GPT-6 Luna: 143
- Claude Haiku 5.5: 167
- Time to first token, s (log scale)
- GPT-6 Luna: 2.4
- Claude Haiku 5.5: 2.1
- AutomationBench+17.8
- AA-Omniscience+4.9
- AA-LCR+0.6
- CritPt+0.5
- FrontierCode+0.1
- SciCode−0.4
- Humanity's Last Exam−5.9
- Terminal-Bench 4.0−20.2
GPT-6 Luna vs Gemini 3.8 Flash
GPT-6 Luna scores higher than Gemini 3.8 Flash in 3 of 8 benchmarks. The widest lead is in FrontierCode: 41.9% against 36.4%. Gemini 3.8 Flash is ahead in AA-Omniscience: 50.5% against 39.6%. GPT-6 Luna writes 143 tokens per second, Gemini 3.8 Flash writes 203
- Benchmarks won
- GPT-6 Luna: 3
- Gemini 3.8 Flash: 5
- Average score
- GPT-6 Luna: 42.9%
- Gemini 3.8 Flash: 46.3%
- Output speed, tokens/s
- GPT-6 Luna: 143
- Gemini 3.8 Flash: 203
- Time to first token, s (log scale)
- GPT-6 Luna: 2.4
- Gemini 3.8 Flash: 7.5
- FrontierCode+5.5
- AA-LCR+2.0
- CritPt+1.1
- SciCode−2.0
- AutomationBench−6.7
- Terminal-Bench 4.0−7.1
- Humanity's Last Exam−9.3
- AA-Omniscience−10.9
GPT-6 Luna vs DeepSeek V4.1 Flash
GPT-6 Luna scores higher than DeepSeek V4.1 Flash in 1 of 8 benchmarks. The widest lead is in AA-LCR: 83.3% against 82.7%. DeepSeek V4.1 Flash is ahead in Terminal-Bench 4.0: 33.8% against 12.6%. GPT-6 Luna writes 143 tokens per second, DeepSeek V4.1 Flash writes 422
- Benchmarks won
- GPT-6 Luna: 1
- DeepSeek V4.1 Flash: 7
- Average score
- GPT-6 Luna: 42.9%
- DeepSeek V4.1 Flash: 48.7%
- Output speed, tokens/s
- GPT-6 Luna: 143
- DeepSeek V4.1 Flash: 422
- Time to first token, s (log scale)
- GPT-6 Luna: 2.4
- DeepSeek V4.1 Flash: 2.2
- AA-LCR+0.6
- AA-Omniscience0.0
- SciCode−1.3
- FrontierCode−1.8
- CritPt−4.6
- Humanity's Last Exam−4.8
- AutomationBench−13.4
- Terminal-Bench 4.0−21.2
Best model by use case
Average benchmark scores of GPT-6 Luna and 4 other models by use case
Coding
?Average of 3 tests- 1GPT-6.1 Terra48.9%
- 2DeepSeek V4.1 Flash44.5%
- 3Claude Haiku 5.543.2%
- 4Gemini 3.8 Flash37.6%
- 5GPT-6 Luna36.4%
Reasoning
?Average of 2 tests- 1GPT-6.1 Terra37.1%
- 2DeepSeek V4.1 Flash33.6%
- 3Gemini 3.8 Flash33.0%
- 4Claude Haiku 5.531.6%
- 5GPT-6 Luna28.9%
Knowledge work
?Average of 2 tests- 1Gemini 3.8 Flash65.9%
- 2GPT-6.1 Terra65.2%
- 3GPT-6 Luna61.5%
- 4DeepSeek V4.1 Flash61.2%
- 5Claude Haiku 5.558.7%
Agents
?AutomationBench- 1DeepSeek V4.1 Flash66.6%
- 2GPT-6.1 Terra60.2%
- 3Gemini 3.8 Flash59.9%
- 4GPT-6 Luna53.2%
- 5Claude Haiku 5.535.4%
GPT-6 Luna benchmarks
Compare GPT-6 Luna with 4 other models in 8 benchmarks measuring coding, reasoning, knowledge work and agents
Coding
- Terminal-Bench 4.0?GPT-6 Luna12.6%GPT-6.1 Terra55.6%Claude Haiku 5.532.8%Gemini 3.8 Flash19.7%DeepSeek V4.1 Flash33.8%12.6%−43.0
- SciCode?GPT-6 Luna54.6%GPT-6.1 Terra55.1%Claude Haiku 5.555.0%Gemini 3.8 Flash56.6%DeepSeek V4.1 Flash55.9%54.6%−2.0
- FrontierCode?GPT-6 Luna41.9%GPT-6.1 Terra36.0%Claude Haiku 5.541.8%Gemini 3.8 Flash36.4%DeepSeek V4.1 Flash43.7%41.9%−1.8
Reasoning
- Humanity's Last Exam?GPT-6 Luna38.5%GPT-6.1 Terra46.2%Claude Haiku 5.544.4%Gemini 3.8 Flash47.8%DeepSeek V4.1 Flash43.3%38.5%−9.3
- CritPt?GPT-6 Luna19.4%GPT-6.1 Terra28.0%Claude Haiku 5.518.9%Gemini 3.8 Flash18.3%DeepSeek V4.1 Flash24.0%19.4%−8.6
Knowledge work
- AA-LCR?GPT-6 Luna83.3%GPT-6.1 Terra82.7%Claude Haiku 5.582.7%Gemini 3.8 Flash81.3%DeepSeek V4.1 Flash82.7%83.3%+0.6
- AA-Omniscience?GPT-6 Luna39.6%GPT-6.1 Terra47.6%Claude Haiku 5.534.7%Gemini 3.8 Flash50.5%DeepSeek V4.1 Flash39.6%39.6%−10.9
Agents
- AutomationBench?GPT-6 Luna53.2%GPT-6.1 Terra60.2%Claude Haiku 5.535.4%Gemini 3.8 Flash59.9%DeepSeek V4.1 Flash66.6%53.2%−13.4
Sources: OpenAI, Introducing GPT-6 Sol and Luna (Sep 22, 2026), Artificial Analysis, GPT-6 Luna
GPT-6 Luna speed
Output speed is how fast the model writes (tokens per second, higher is better). Time to first token is how long you wait before the answer starts (lower is better)
Output speed and time to first token of 35 models
?Percentile| Models | Output speed, tokens/s (log scale) | Time to first token, s (log scale) |
|---|---|---|
| GPT-6 Luna | 143 | 2.4 |
| GPT-6.1 Terra | 75 | 4.3 |
| GPT-6.1 Sol | 58 | 2.9 |
| GPT-6 Astra | 48 | 3.2 |
| Claude Opus 5.5 | 88 | 1.9 |
| Claude Opus 5 | 54 | 2.6 |
| Claude Opus 4.8 | 59 | 1.3 |
| Claude Fable 5.2 | 84 | 2.3 |
| Claude Sonnet 5.5 | 102 | 1 |
| Claude 5 Sonnet | 215 | 10.5 |
| Claude Sonnet 4.6 | 220 | 10.8 |
| Claude Haiku 5.5 | 167 | 2.1 |
| Gemini 4 Carbon | 169 | 29.5 |
| Gemini 4 Argon | 91 | 6 |
| Gemini 3.8 Flash | 203 | 7.5 |
| Gemini 3 Pro | 270 | 11.2 |
| Grok 4.7 | 81 | 8.9 |
| Grok 4.6 | 290 | 32 |
| Qwen 3.8 Max | 81 | 30.6 |
| DeepSeek V4 Pro | 144 | 1.1 |
| DeepSeek V4.1 Flash | 422 | 2.2 |
| Mistral Large 4 | 226 | 8.6 |
| Hy4 | 214 | 37.7 |
| ERNIE 5.5 Flash | 405 | 2.7 |
| Muse Wonder | 980 | 8.7 |
| Muse Spark | 1129 | 6.2 |
| Kimi K3.1 Pro | 340 | 7.4 |
| Kimi K3 | 338 | 5.9 |
| GLM 5.3 | 197 | 1.2 |
| Flint | 194 | 12.3 |
| Llama 4 | 81 | 0.7 |
| Claude 4.5 Haiku | 162 | 0.9 |
| MiniMax M3 | 169 | 4.5 |
| MiniMax M3.1 Flash | 656 | 7.2 |
| Kimi K2.7 Code | 455 | 3.6 |
Typing test
Every model writes the same answer. The test waits the model's time to first token, then prints the text at the model's output speed and shows the total time
- GPT-6 Luna143 tokens/s2.4 s to first token
- GPT-6.1 Terra75 tokens/s4.3 s to first token
- Claude Haiku 5.5167 tokens/s2.1 s to first token
- Gemini 3.8 Flash203 tokens/s7.5 s to first token
Source: Overchat AI, 2026-11-11
See how GPT-6 Luna answers
Examples of GPT-6 Luna answers to 3 prompts: Pull out action items, Write an email and Fix my JavaScript. Each answer is the unedited output of the model
Pull every action item out of these meeting notes as a table with the task, the owner and the due date: Kickoff with the design team, Monday. Anna will send the new logo options by Thursday. We agreed the landing page copy is Mark's job, first draft next Wednesday. Budget for ads is still open, Priya checks it with finance before the end of the month. Next sync in two weeks, Leo books the room.
GPT-6 Luna| Task | Owner | Due date |
|---|---|---|
| Kick off with the design team | Not specified | Monday |
| Send the new logo options | Anna | Thursday |
| Prepare the first draft of the landing page copy | Mark | Next Wednesday |
| Check the ad budget with finance | Priya | Before the end of the month |
| Book the room for the next sync | Leo | Before the next sync, in two weeks |
Write a short, polite email to my landlord asking to fix the broken heater this week. It has been cold in the apartment for three days.
GPT-6 LunaSubject: Heater Repair Request
Hi [Landlord’s Name],
Could you please arrange to have the broken heater fixed this week? The apartment has been cold for the past three days, and I’d appreciate your help resolving this as soon as possible.
Thank you,
[Your Name]
My JavaScript prints [object Promise] instead of the user data. Explain why in two sentences and fix it: const data = fetch('/api/user').then(r => r.json()); console.log(data.name);
GPT-6 Lunafetch() is asynchronous, so data is a Promise and data.name is accessed before the user data has arrived. Use await inside an async function:
async function loadUser() {
  const response = await fetch('/api/user');
  const data = await response.json();
  console.log(data.name);
}

loadUser();More prompts to try with GPT-6 Luna
What GPT-6 Luna is best for
Everyday writing
GPT-6 Luna writes emails, messages, posts and replies in seconds, at about 140 tokens a second on Overchat AI
Notes and long documents
Paste meeting notes, a contract or a long report, and GPT-6 Luna pulls out what matters. It scores 83.3% on AA-LCR, a test of reasoning over very long documents, ranking #9 of 183 models
Coding help
GPT-6 Luna explains errors and fixes code, with 66.6% on DeepSWE v1.1, a test of real software tasks, close to Claude Opus 5 at medium effort
Photos and files
Attach a photo, a screenshot or a PDF and ask about it. GPT-6 Luna scores 79.7% on MMMU Pro, a test of questions about charts, diagrams and photos
How to use GPT-6 Luna on Overchat AI
Start in the chat at the top of this page or in the Overchat AI app on the web, iOS or Android
- 01
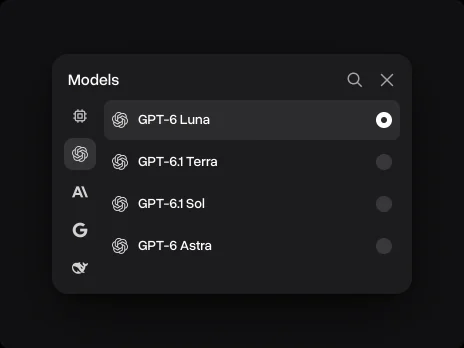
Pick GPT-6 Luna
It is already picked in the chat on this page. In the Overchat AI app, open the model list next to the message field and pick GPT-6 Luna
- 02
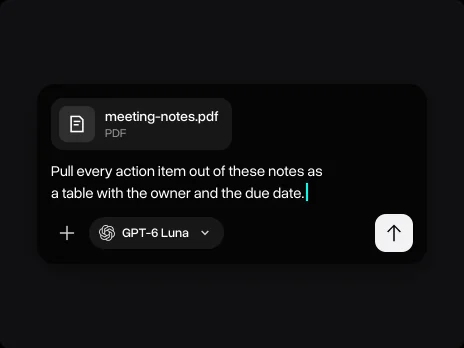
Attach your code or a file
Add code, a document, a spreadsheet or a screenshot, and write what you need: the result, the format and what must stay the same
- 03
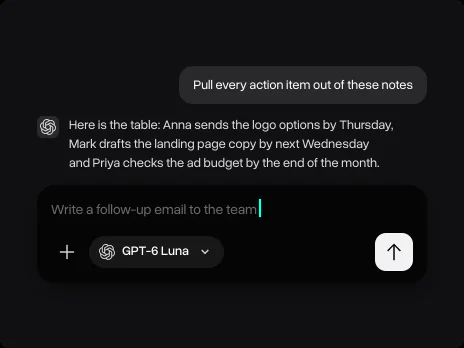
Keep going in the same chat
Ask a follow-up, ask for tests or a shorter version, or switch to another model without losing the conversation
Why use GPT-6 Luna on Overchat AI
One account for chat, images and video, on every device
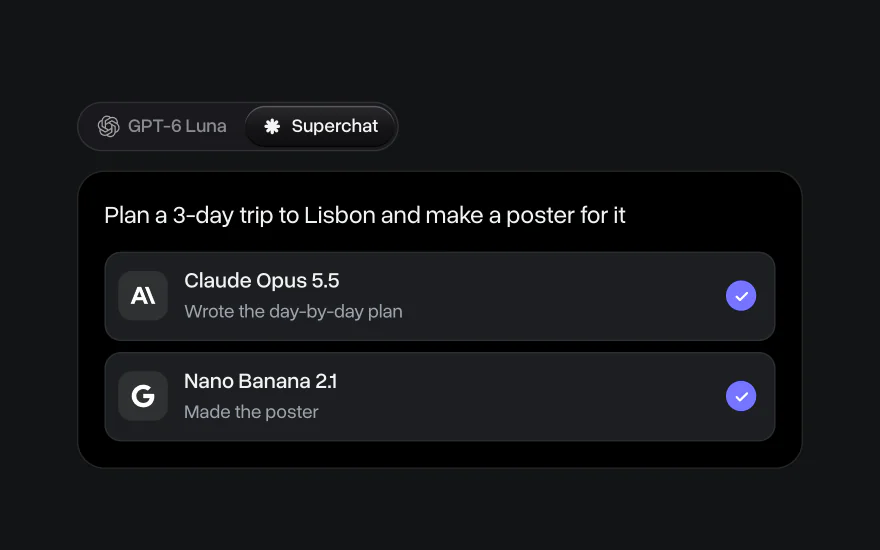
Superchat AI agent
Superchat Agent automatically routes your message to the model best suited for the task. It can generate images and videos, use the AI tools built into Overchat AI, and learn from your interactions to get better over time
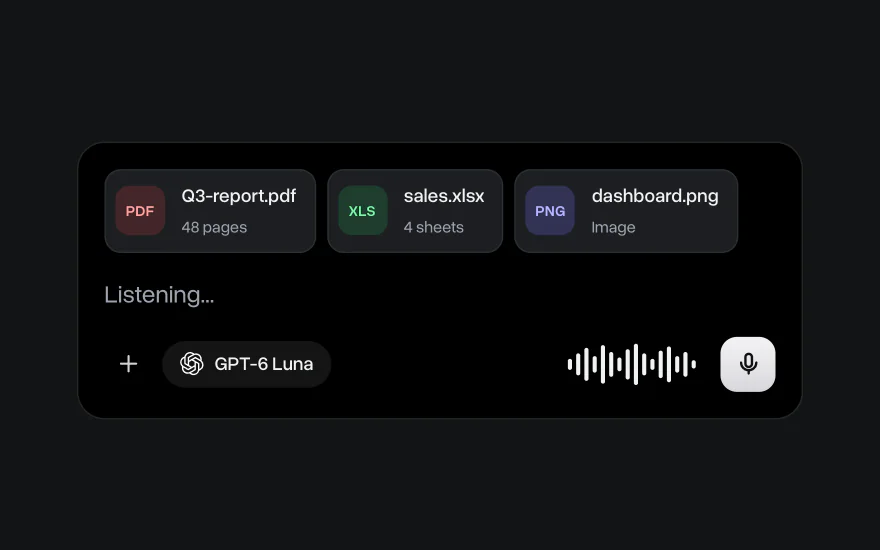
Chat with images and files
Upload PDFs, spreadsheets, code and screenshots and ask GPT-6 Luna about them. You can also dictate a message instead of typing it
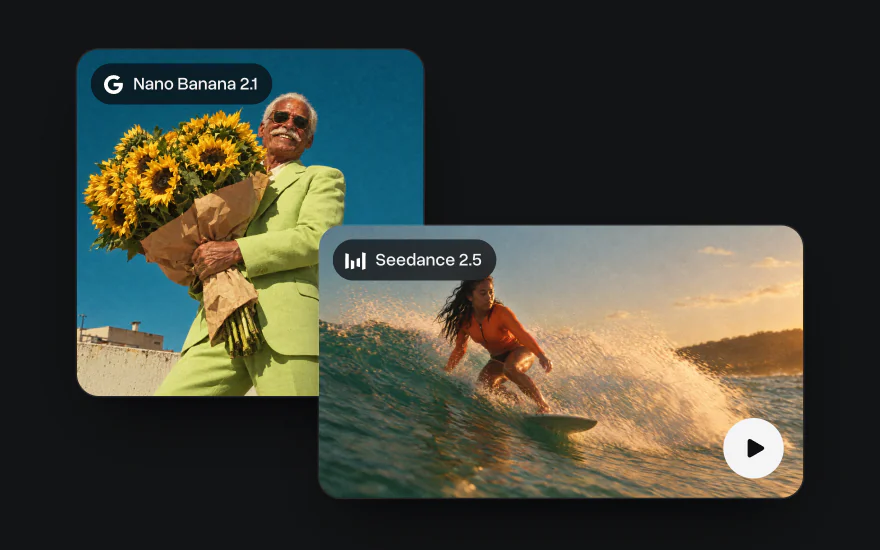
Go beyond text
Generate images with Nano Banana and GPT Image and videos with Seedance and Kling in the same account, with the same credits as chat
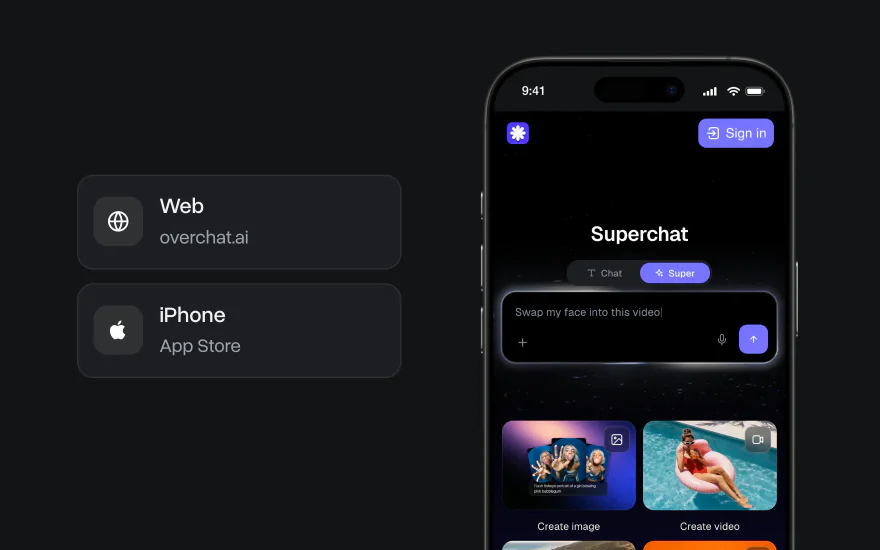
On the web and iPhone
Start a chat on your laptop and finish it on your phone. The Overchat AI app has the same models, and your chats stay in one account on every device
GPT models on Overchat AI
Compare 4 GPT models on Overchat AI by output speed, time to first token and the price of one message
GPT-6 LunaThis pageGPT-6 AstraSource: Overchat AI, 2026-11-11
Explore other models
Models marked Soon are coming to Overchat AI; the rest are available now


Learn more about AI models

We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder
We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder on three coding tasks. See benchmarks, speed and how to use it
Muse Wonder vs Muse Spark: Meta's New Model Tested
We tested Muse Wonder against Muse Spark 1.3 on logic, writing and coding tasks. See benchmarks and which Meta model is better
10 Best All-in-One AI Platforms in 2026: Why One AI Subscription Beats Many
Compare the 10 best all-in-one AI platforms in 2026, from Overchat AI to Poe and Magai, with prices, free plans and the newest GPT and Claude models



