


About Claude Opus 5.5
Claude Opus 5.5 is Anthropic's flagship model for long coding jobs, code review and knowledge work, released on September 22, 2026. It reads up to 1 million tokens of text, code, images and files in one conversation, writes up to 128,000 tokens in one reply and thinks longer on hard problems than on simple ones
Claude Opus 5.5 scores 66.4% on Terminal-Bench 4.0, ahead of GPT-6 Astra at 57.9% and Claude Fable 5.1 at 55.8%, and 1846 Elo on GDPval-AA, a test of real work from 44 occupations. It audits and migrates whole codebases, finds bugs across files and writes short, clear answers with the main point first
On Overchat AI, Claude Opus 5.5 is in one chat with GPT-6, Gemini, Grok and DeepSeek, so you can check an answer with another model without starting a new conversation
- Modalities
- Intelligence Index?
- 59
- Context window?
- 1M tokens
- Released
- Sep 22, 2026
Claude Opus 5.5 vs other models
Claude Opus 5.5 ranks #3 on the Artificial Analysis Intelligence Index out of 54 models
- 65
 Claude Fable 5.2
- 60
 Gemini 4 Carbon
- 59Claude Opus 5.5
- 57
 GPT-6 Astra
- 55GPT-6.1 Sol
- 50
 Muse Wonder Full
- 46
 Kimi K3.1 Pro
- 44Muse Wonder
- 35
 Grok 4.7
- 33
 DeepSeek V4.1 Flash
- #2of 136 modelsSciCodePython code for scientific computing
- #3of 63 modelsAA-OmniscienceKnowledge questions answered correctly
- #3of 288 modelsCritPtResearch-level physics problems
- #6of 292 modelsAA-LCRQuestions that need reasoning over very long documents
Source: Artificial Analysis
Compare Claude Opus 5.5
Claude Opus 5.5 vs Claude Fable 5.1
Claude Opus 5.5 scores higher than Claude Fable 5.1 in 8 of 8 benchmarks. The widest lead is in Terminal-Bench 4.0: 66.4% against 55.8%
- Benchmarks won
- Claude Opus 5.5: 8
- Claude Fable 5.1: 0
- Average score
- Claude Opus 5.5: 64.5%
- Claude Fable 5.1: 59.6%
- Terminal-Bench 4.0+10.6
- AutomationBench+8.6
- Terminal-Bench-Science 0.1+6.1
- CursorBench 4.0+6.0
- FrontierCode v1.1+4.1
- Humanity's Last Exam+2.1
- OSWorld 2.1+1.1
- Chartography+0.6
Claude Opus 5.5 vs GPT-6 Astra
Claude Opus 5.5 scores higher than GPT-6 Astra in 3 of 5 benchmarks. The widest lead is in Humanity's Last Exam: 67.7% against 57.2%. GPT-6 Astra is ahead in Terminal-Bench-Science 0.1: 64.6% against 58.7%. Claude Opus 5.5 writes 88 tokens per second, GPT-6 Astra writes 48
- Benchmarks won
- Claude Opus 5.5: 3
- GPT-6 Astra: 2
- Average score
- Claude Opus 5.5: 57.4%
- GPT-6 Astra: 54.9%
- Output speed, tokens/s
- Claude Opus 5.5: 88
- GPT-6 Astra: 48
- Time to first token, s (log scale)
- Claude Opus 5.5: 1.9
- GPT-6 Astra: 3.2
- Humanity's Last Exam+10.5
- Terminal-Bench 4.0+8.5
- FrontierCode v1.1+1.1
- AutomationBench−1.4
- Terminal-Bench-Science 0.1−5.9
- CursorBench 4.0—
- OSWorld 2.1—
- Chartography—
Best model by use case
Average benchmark scores of Claude Opus 5.5 and 2 other models by use case
Coding
?Average of 3 tests- 1Claude Opus 5.559.8%
- 2GPT-6 Astra58.6%
- 3Claude Fable 5.152.9%
Agents
?AutomationBench- 1GPT-6 Astra41.4%
- 2Claude Opus 5.540.0%
- 3Claude Fable 5.131.4%
Knowledge work
?Humanity's Last Exam- 1Claude Opus 5.567.7%
- 2Claude Fable 5.165.6%
- 3GPT-6 Astra57.2%
Claude Opus 5.5 benchmarks
Compare Claude Opus 5.5 with Claude Fable 5.1 and GPT-6 Astra in 9 benchmarks measuring coding, agents and knowledge work
Coding
- Terminal-Bench 4.0?Claude Opus 5.566.4%Claude Fable 5.155.8%GPT-6 Astra57.9%66.4%+8.5
- FrontierCode v1.1?Claude Opus 5.554.4%Claude Fable 5.150.3%GPT-6 Astra53.3%54.4%+1.1
- CursorBench 4.0?Claude Opus 5.557.8%Claude Fable 5.151.8%GPT-6 Astra—57.8%+6.0
- Terminal-Bench-Science 0.1?Claude Opus 5.558.7%Claude Fable 5.152.6%GPT-6 Astra64.6%58.7%−5.9
Agents
- OSWorld 2.1?Claude Opus 5.581.8%Claude Fable 5.180.7%GPT-6 Astra—81.8%+1.1
- AutomationBench?Claude Opus 5.540.0%Claude Fable 5.131.4%GPT-6 Astra41.4%40.0%−1.4
Knowledge work
- GDPval-AA v2.1?Claude Opus 5.51846.0%Claude Fable 5.11735.0%GPT-6 Astra1542.0%1846.0%+111.0
- Humanity's Last Exam?Claude Opus 5.567.7%Claude Fable 5.165.6%GPT-6 Astra57.2%67.7%+2.1
- Chartography?Claude Opus 5.589.0%Claude Fable 5.188.4%GPT-6 Astra—89.0%+0.6
Sources: Anthropic, Introducing Claude Opus 5.5 (Sep 22, 2026), Artificial Analysis, Claude Opus 5.5
Claude Opus 5.5 speed
Output speed is how fast the model writes (tokens per second, higher is better). Time to first token is how long you wait before the answer starts (lower is better)
Output speed and time to first token of 35 models
?Percentile| Models | Output speed, tokens/s (log scale) | Time to first token, s (log scale) |
|---|---|---|
| GPT-6 Luna | 143 | 2.4 |
| GPT-6.1 Terra | 75 | 4.3 |
| GPT-6.1 Sol | 58 | 2.9 |
| GPT-6 Astra | 48 | 3.2 |
| Claude Opus 5.5 | 88 | 1.9 |
| Claude Opus 5 | 54 | 2.6 |
| Claude Opus 4.8 | 59 | 1.3 |
| Claude Fable 5.2 | 84 | 2.3 |
| Claude Sonnet 5.5 | 102 | 1 |
| Claude 5 Sonnet | 215 | 10.5 |
| Claude Sonnet 4.6 | 220 | 10.8 |
| Claude Haiku 5.5 | 167 | 2.1 |
| Gemini 4 Carbon | 169 | 29.5 |
| Gemini 4 Argon | 91 | 6 |
| Gemini 3.8 Flash | 203 | 7.5 |
| Gemini 3 Pro | 270 | 11.2 |
| Grok 4.7 | 81 | 8.9 |
| Grok 4.6 | 290 | 32 |
| Qwen 3.8 Max | 81 | 30.6 |
| DeepSeek V4 Pro | 144 | 1.1 |
| DeepSeek V4.1 Flash | 422 | 2.2 |
| Mistral Large 4 | 226 | 8.6 |
| Hy4 | 214 | 37.7 |
| ERNIE 5.5 Flash | 405 | 2.7 |
| Muse Wonder | 980 | 8.7 |
| Muse Spark | 1129 | 6.2 |
| Kimi K3.1 Pro | 340 | 7.4 |
| Kimi K3 | 338 | 5.9 |
| GLM 5.3 | 197 | 1.2 |
| Flint | 194 | 12.3 |
| Llama 4 | 81 | 0.7 |
| Claude 4.5 Haiku | 162 | 0.9 |
| MiniMax M3 | 169 | 4.5 |
| MiniMax M3.1 Flash | 656 | 7.2 |
| Kimi K2.7 Code | 455 | 3.6 |
Typing test
Every model writes the same answer. The test waits the model's time to first token, then prints the text at the model's output speed and shows the total time
- Claude Opus 5.588 tokens/s1.9 s to first token
- GPT-6 Astra48 tokens/s3.2 s to first token
Source: Overchat AI, 2026-11-11
See how Claude Opus 5.5 answers
Examples of Claude Opus 5.5 answers to 3 prompts: Find a bug, Summarize a thread and Check the numbers. Each answer is the unedited output of the model
This function should return the total usage for a billing month, but customers say the last day of the month is never billed. Find the bug, explain it in two sentences and give the fixed code. ```python from datetime import datetime, timedelta def month_bounds(year, month): start = datetime(year, month, 1) nxt = datetime(year + month // 12, month % 12 + 1, 1) return start, nxt - timedelta(days=1) def monthly_usage(events, year, month): start, end = month_bounds(year, month) return sum(e.amount for e in events if start <= e.ts <= end) ```
Claude Opus 5.5Bug: month_bounds returns nxt - timedelta(days=1) as the end bound, which is midnight at the start of the last day (e.g. 2024-01-31 00:00:00), not the end of it. Because the filter uses e.ts <= end, every event after 00:00:00 on the last day is excluded, so that day's usage is effectively never billed.
Fix: Use a half-open interval [start of month, start of next month).
from datetime import datetime

def month_bounds(year, month):
    start = datetime(year, month, 1)
    nxt = datetime(year + month // 12, month % 12 + 1, 1)
    return start, nxt  # end is exclusive: first instant of next month

def monthly_usage(events, year, month):
    start, end = month_bounds(year, month)
    return sum(e.amount for e in events if start <= e.ts < end)
The half-open interval also avoids precision problems that come with an inclusive end such as 23:59:59, which would miss events with microseconds after that second. The existing year-rollover logic for December is correct and stays unchanged.
Summarize this Slack thread for my manager in three short bullet points: the problem, what's fixed and what's left. Lena: The checkout page broke for Safari users after Tuesday's release. About 12% of orders failed for two days. Omar: The cause is a date-picker library update. I rolled it back this morning and Safari checkouts work again. Lena: Support has 340 tickets about failed payments. Can we refund the extra charges? Mei: Finance confirmed 58 customers were charged twice. Refunds go out today. Omar: I'm adding a Safari run to our release tests so this can't ship again. Ready by Friday. Lena: I'll email the affected customers a 10% coupon once the refunds land.
Claude Opus 5.5- Problem: Tuesday's release broke checkout for Safari users, and about 12% of orders failed over two days. The cause was a date-picker library update. Support has received 340 tickets, and 58 customers were charged twice.
- Fixed: Omar rolled back the library update this morning, and Safari checkouts are working again.
- Still to do: Finance is sending refunds to the 58 double-charged customers today. Omar is adding Safari to release testing to prevent a repeat, due Friday. Lena will email affected customers a 10% coupon once the refunds land.
Our startup has $1.1M in the bank, $40k monthly revenue growing 8% a month, and $120k monthly costs that stay flat. In which month do we break even, and do we run out of money before that? Show the math in a short table.
Claude Opus 5.5Break-even in Month 16, with about $386k left at the low point
Assumptions: Month 1 revenue is $40k, and revenue grows 8% each month after that. Costs stay flat at $120k/month.
Break-even condition: 40 × 1.08ⁿ⁻¹ ≥ 120 → 1.08ⁿ⁻¹ ≥ 3 → n − 1 ≥ ln 3 / ln 1.08 ≈ 14.3 → n = 16
| Month | Revenue ($k) | Costs ($k) | Net ($k) | Cash End ($k) |
|---|---|---|---|---|
| 1 | 40.0 | 120 | −80.0 | 1,020.0 |
| 2 | 43.2 | 120 | −76.8 | 943.2 |
| 3 | 46.7 | 120 | −73.3 | 869.9 |
| 4 | 50.4 | 120 | −69.6 | 800.2 |
| 5 | 54.4 | 120 | −65.6 | 734.7 |
| 6 | 58.8 | 120 | −61.2 | 673.4 |
| 7 | 63.5 | 120 | −56.5 | 616.9 |
| 8 | 68.6 | 120 | −51.4 | 565.5 |
| 9 | 74.0 | 120 | −46.0 | 519.5 |
| 10 | 80.0 | 120 | −40.0 | 479.5 |
| 11 | 86.4 | 120 | −33.6 | 445.8 |
| 12 | 93.3 | 120 | −26.7 | 419.1 |
| 13 | 100.7 | 120 | −19.3 | 399.8 |
| 14 | 108.8 | 120 | −11.2 | 388.6 |
| 15 | 117.5 | 120 | −2.5 | 386.1 (low point) |
| 16 | 126.9 | 120 | +6.9 | 393.0 |
Total burn before break-even is about $714k. Over months 1–15, revenue sums to 40 × (1.08¹⁵ − 1)/0.08 ≈ $1,086k, against $1,800k in costs.
Answer: You break even in Month 16 (or Month 15 if the 8% growth starts next month). You don't run out of money. Cash bottoms out around $386k, which is roughly 35% of what you have now.
Sensitivity: The cushion is real but depends on growth holding up. At about 5% monthly growth, break-even slips to around Month 24 and the cash runs out before you get there.
More prompts to try with Claude Opus 5.5
What Claude Opus 5.5 is best for
Long coding jobs
Claude Opus 5.5 takes on migrations, audits and refactors that span a whole codebase and keeps working until the tests pass. It scores 66.4% on Terminal-Bench 4.0 and 57.8% on CursorBench 4.0, ahead of Claude Fable 5.1 and Opus 5
Code review and bug fixing
Paste a diff or attach a file, and Opus 5.5 points to the line that breaks, explains why in plain words and writes the fix. It looks past the first plausible cause and checks how the parts of the code fit together
Reports, models and analysis
Give Opus 5.5 notes, numbers and documents, and it returns a report, a financial model or a slide outline. It scores 1846 Elo on GDPval-AA, ahead of Claude Fable 5.1 at 1735 and GPT-6 Astra at 1542
Clear summaries
Opus 5.5 writes short answers with the most important point first and no jargon, so a long thread, a meeting or a report turns into a summary your manager reads in a minute
How to use Claude Opus 5.5 on Overchat AI
Start in the chat at the top of this page or in the Overchat AI app on the web, iOS or Android
- 01
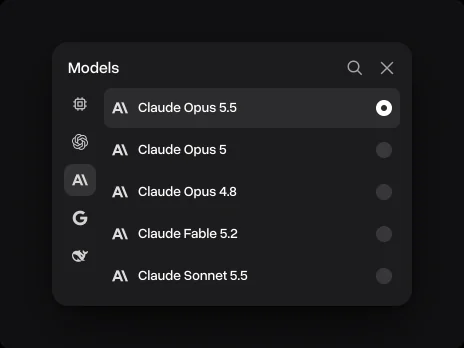
Pick Claude Opus 5.5
It is already picked in the chat on this page. In the Overchat AI app, open the model list next to the message field and pick Claude Opus 5.5
- 02
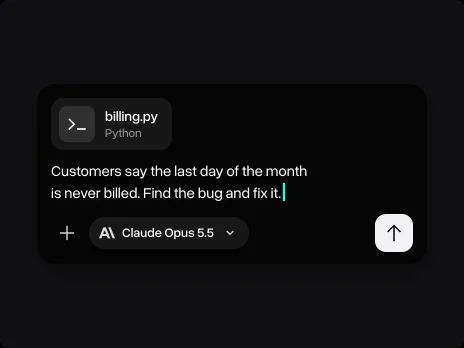
Attach your code or a file
Add code, a document, a spreadsheet or a screenshot, and write what you need: the result, the format and what must stay the same
- 03
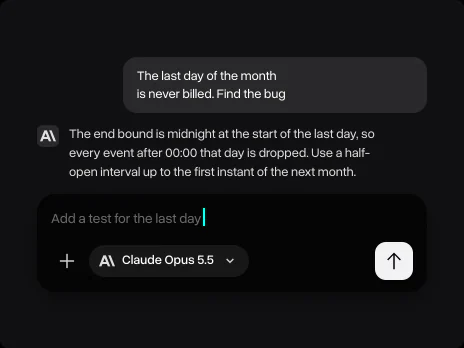
Keep going in the same chat
Ask a follow-up, ask for tests or a shorter version, or switch to another model without losing the conversation
Why use Claude Opus 5.5 on Overchat AI
One account for chat, images and video, on every device
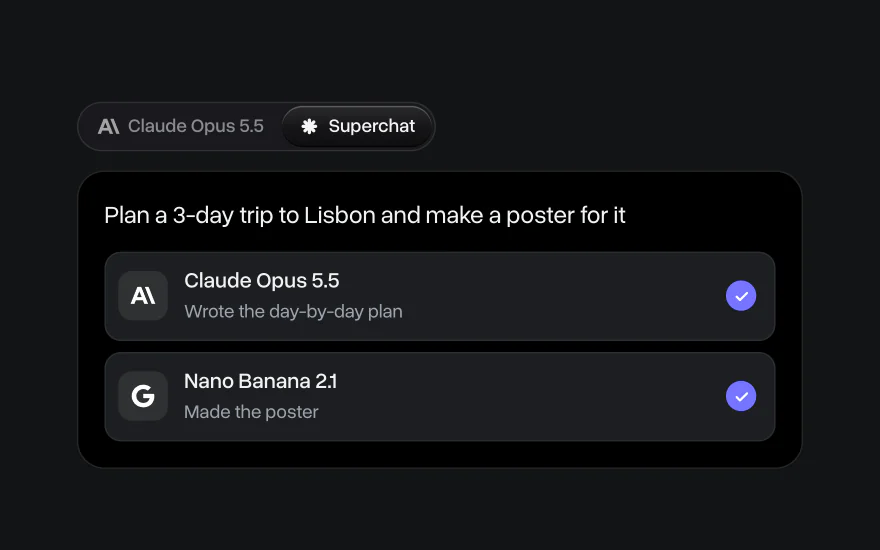
Superchat AI agent
Superchat Agent automatically routes your message to the model best suited for the task. It can generate images and videos, use the AI tools built into Overchat AI, and learn from your interactions to get better over time
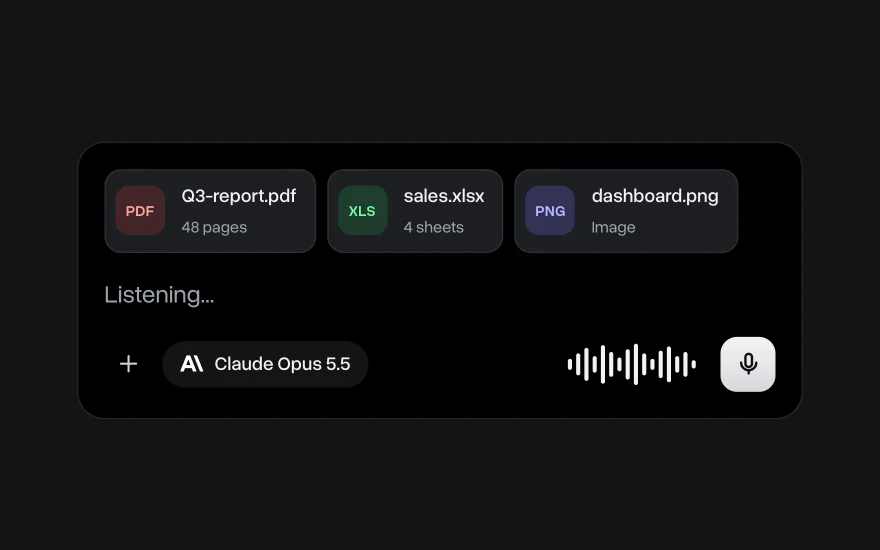
Chat with images and files
Upload PDFs, spreadsheets, code and screenshots and ask Claude Opus 5.5 about them. You can also dictate a message instead of typing it
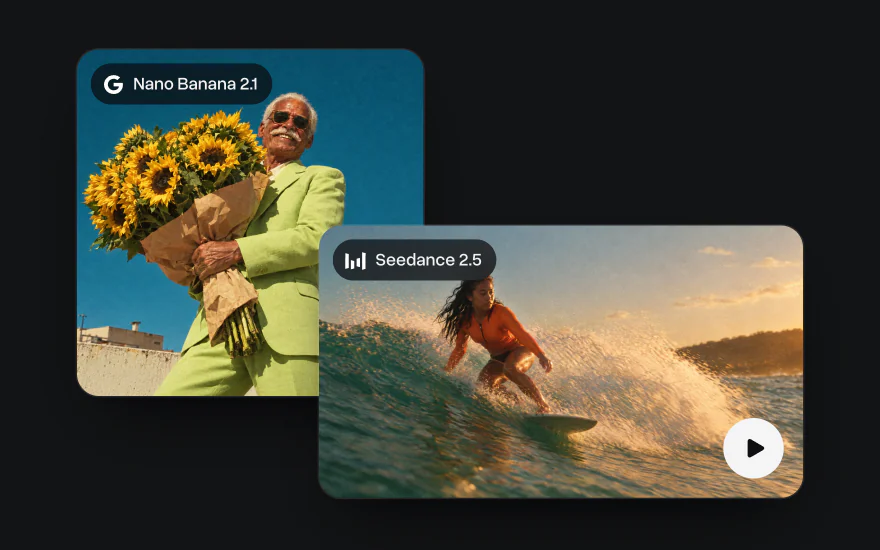
Go beyond text
Generate images with Nano Banana and GPT Image and videos with Seedance and Kling in the same account, with the same credits as chat
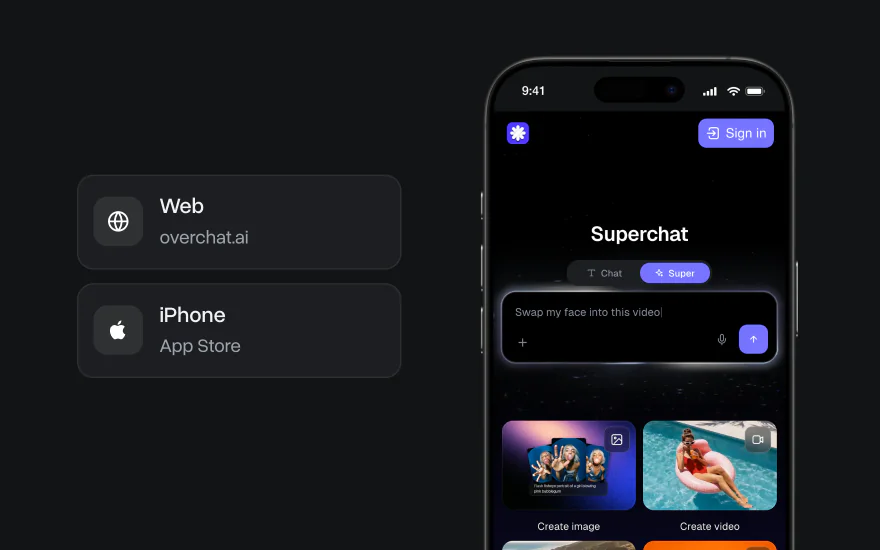
On the web and iPhone
Start a chat on your laptop and finish it on your phone. The Overchat AI app has the same models, and your chats stay in one account on every device
Claude models on Overchat AI
Compare 9 Claude models on Overchat AI by output speed, time to first token and the price of one message
Claude Opus 5.5This pageClaude Sonnet 5.5Claude Sonnet 4.6Claude Haiku 5.5Claude 4.5 HaikuSource: Overchat AI, 2026-11-11
Explore other models
Models marked Soon are coming to Overchat AI; the rest are available now


Learn more about AI models

We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder
We tested Gemini 4 Argon against Claude Opus 5.5, GPT-6 Astra and Muse Wonder on three coding tasks. See benchmarks, speed and how to use it
Muse Wonder vs Muse Spark: Meta's New Model Tested
We tested Muse Wonder against Muse Spark 1.3 on logic, writing and coding tasks. See benchmarks and which Meta model is better
10 Best All-in-One AI Platforms in 2026: Why One AI Subscription Beats Many
Compare the 10 best all-in-one AI platforms in 2026, from Overchat AI to Poe and Magai, with prices, free plans and the newest GPT and Claude models



